MOSS-Audio: 8B Parameters Challenge 30B, New Benchmark for Open-Source Audio Understanding Models
Understanding a piece of audio is far more complex than simply "converting speech to text."
A real audio clip may contain speech, background environmental sounds, music, emotional shifts, and even overlapping multi-speaker conversations. A truly capable audio understanding system must simultaneously identify who is speaking, detect emotional states, interpret background sounds, analyze musical content, and answer time-aware questions like "what did the speaker say at the 2-minute mark?"
In April 2026, the OpenMOSS team, together with MOSI.AI and Shanghai Technology Innovation Strategic Company, released MOSS-Audio — an open-source audio understanding model that unifies speech, environmental sound, music understanding, and time-aware reasoning into a single foundation model.
MOSS-Audio-8B outperforms models with several times more parameters across multiple benchmarks, with particularly impressive results on timestamped ASR tasks.
Model Family
Four variants launched at release, all built on Qwen3 language model backbones:
| Model | LLM Backbone | Total Parameters | Optimization Direction |
|---|---|---|---|
| MOSS-Audio-4B-Instruct | Qwen3-4B | ~4.6B | Direct instruction following |
| MOSS-Audio-4B-Thinking | Qwen3-4B | ~4.6B | Chain-of-thought (CoT) reasoning |
| MOSS-Audio-8B-Instruct | Qwen3-8B | ~8.6B | Direct instruction following |
| MOSS-Audio-8B-Thinking | Qwen3-8B | ~8.6B | Chain-of-thought (CoT) reasoning |
The Instruct variants target direct instruction following — structured, predictable outputs ideal for production pipeline integration. The Thinking variants are trained with chain-of-thought reasoning and reinforcement learning, excelling at multi-step reasoning tasks.
Architecture Deep Dive
Overall Architecture
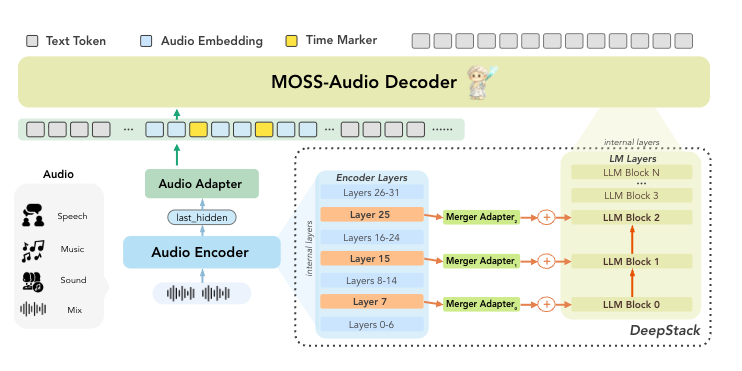
MOSS-Audio uses a modular three-stage design: Audio Encoder → Modal Adapter → Language Model Backbone. Raw audio is encoded as a continuous-time representation at 12.5 Hz, projected into the LLM embedding space, and processed via autoregressive text generation.
Custom Audio Encoder
Unlike many multimodal models that rely on off-the-shelf frontends (e.g., Wav2Vec2, CLAP), MOSS-Audio trains a dedicated audio encoder from scratch. This design yields two advantages: the encoder is jointly optimized across multiple acoustic domains — speech, environmental sounds, and music — avoiding the domain-specific shortcomings of pre-built encoders; and the encoder and language model backbone train more synergistically, reducing the modality gap.
DeepStack Cross-Layer Feature Injection
This is the most noteworthy architectural innovation in MOSS-Audio.
Traditional multimodal architectures typically pass only the top-layer encoder output to the LLM, losing low-level acoustic details (prosody, transients, rhythm, timbre, and background structure) during deep abstraction. MOSS-Audio employs a DeepStack cross-layer injection module:
- Select early-layer and mid-layer features from the encoder
- Independently project and inject them directly into early LLM layers
- Preserve multi-granularity information from low-level acoustic details to high-level semantic abstractions
This design enables the model to maintain semantic understanding without losing sensitivity to subtle acoustic cues — particularly critical for music analysis, emotion recognition, and environmental sound classification.
Time-Aware Representation
Time awareness is the core dimension that distinguishes audio understanding from image understanding. During pre-training, MOSS-Audio inserts explicit time-marker tokens between audio frame representations at fixed time intervals.
The model natively learns "what happened when," natively supporting timestamped ASR, event localization, time-based QA, and long-audio recall without needing extra localization heads or post-processing pipelines.
Benchmark Performance
General Audio Understanding
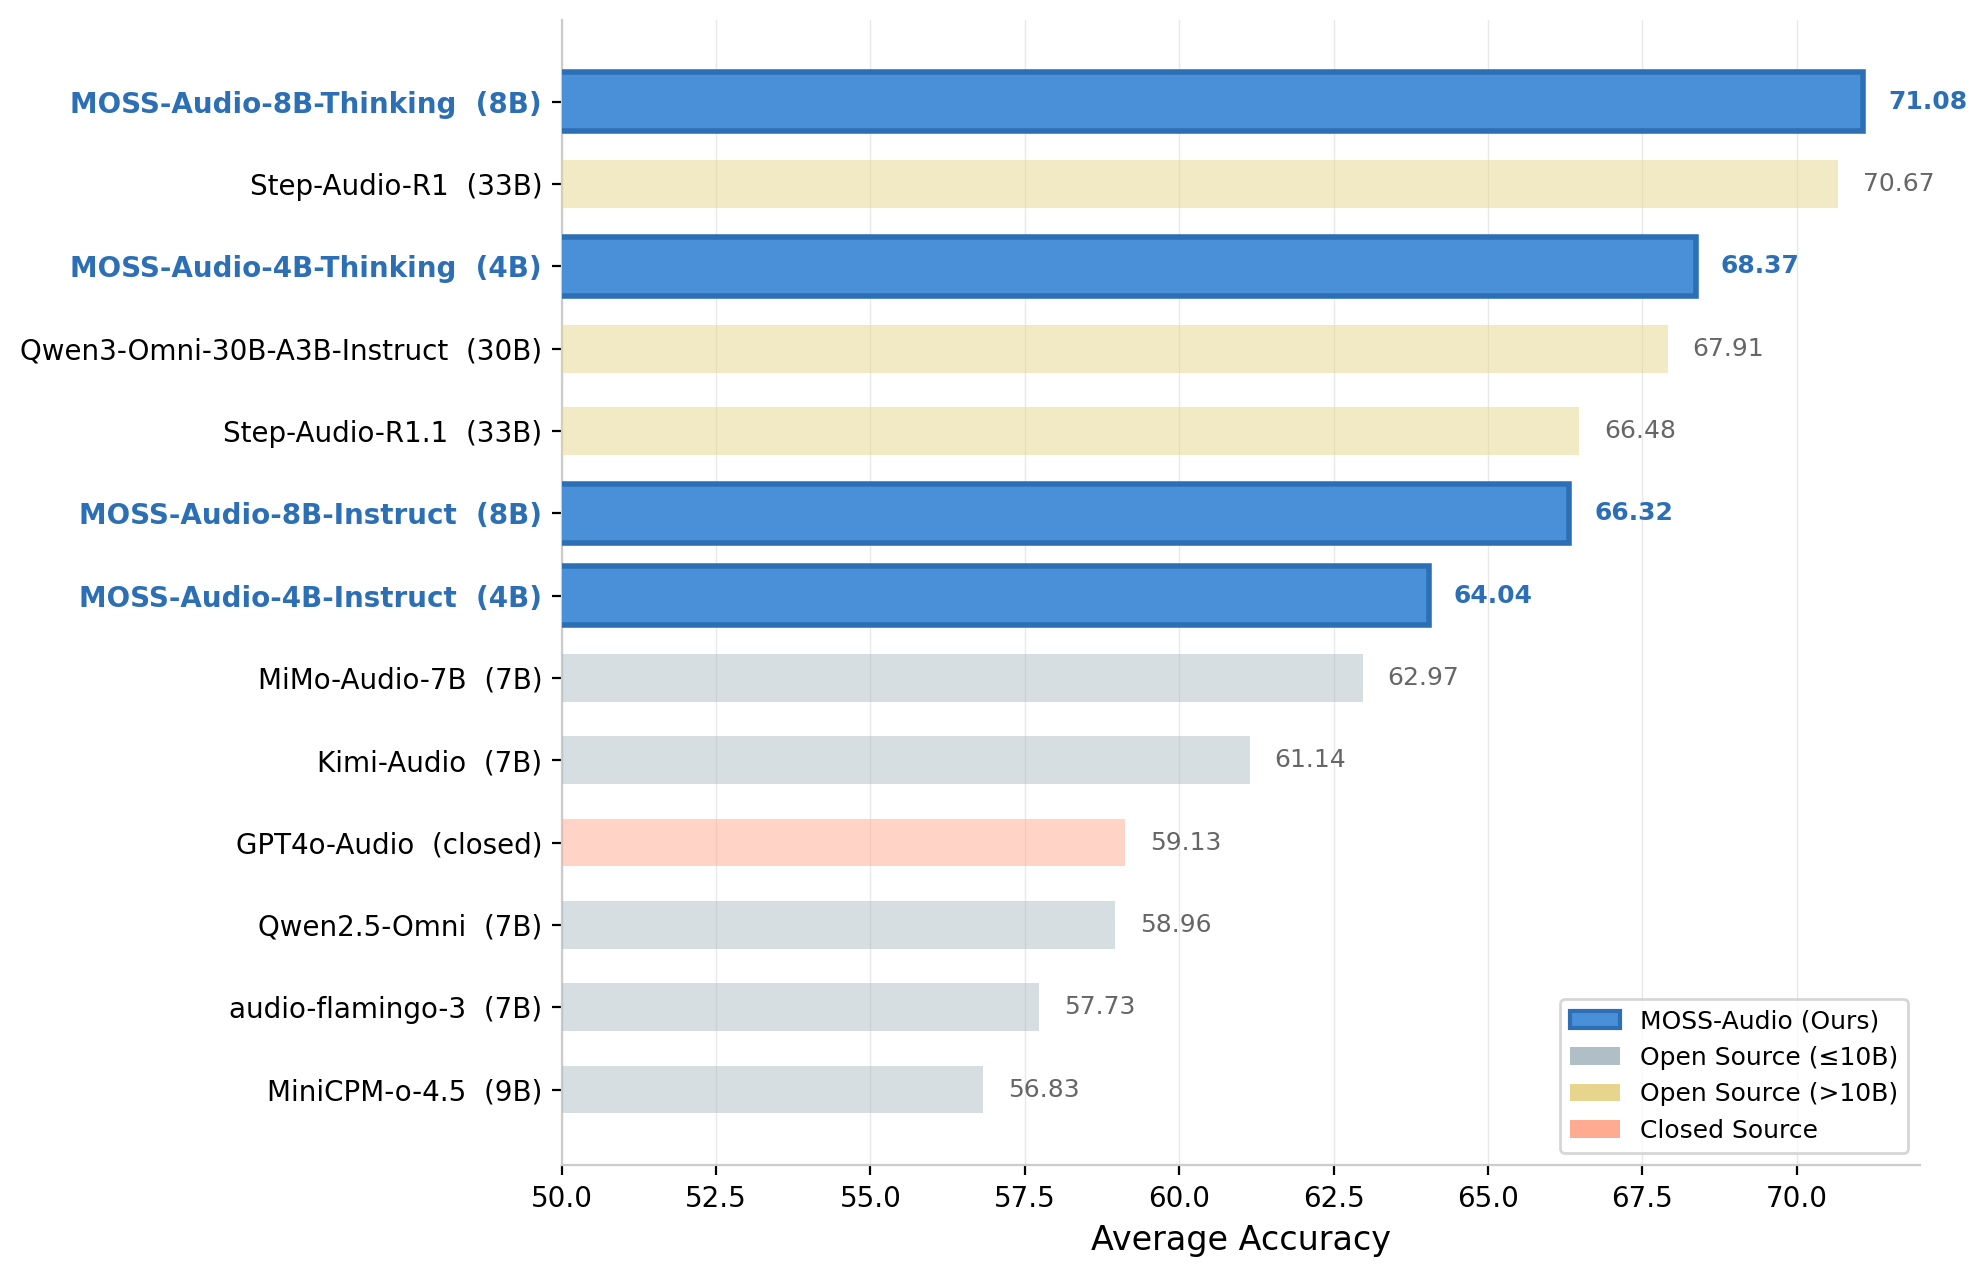
MOSS-Audio-8B-Thinking achieves an average accuracy of 71.08 across four benchmarks:
| Model | Size | MMAU | MMAU-Pro | MMAR | MMSU | Average |
|---|---|---|---|---|---|---|
| MOSS-Audio-8B-Thinking | 8B | 77.33 | 64.92 | 66.53 | 75.52 | 71.08 |
| Step-Audio-R1 | 33B | 78.67 | 59.68 | 69.15 | 75.18 | 70.67 |
| Qwen3-Omni-30B | 30B | 72.06 | 61.22 | 66.40 | 69.00 | 67.91 |
| MOSS-Audio-4B-Thinking | 4B | 75.78 | 63.13 | 64.83 | 73.88 | 68.37 |
MOSS-Audio-4B-Thinking (68.37) already surpasses all open-source competitors at 7B/9B scale. The 8B version beats the 33B Step-Audio-R1 on MMAU-Pro and MMAR.
Speech Captioning
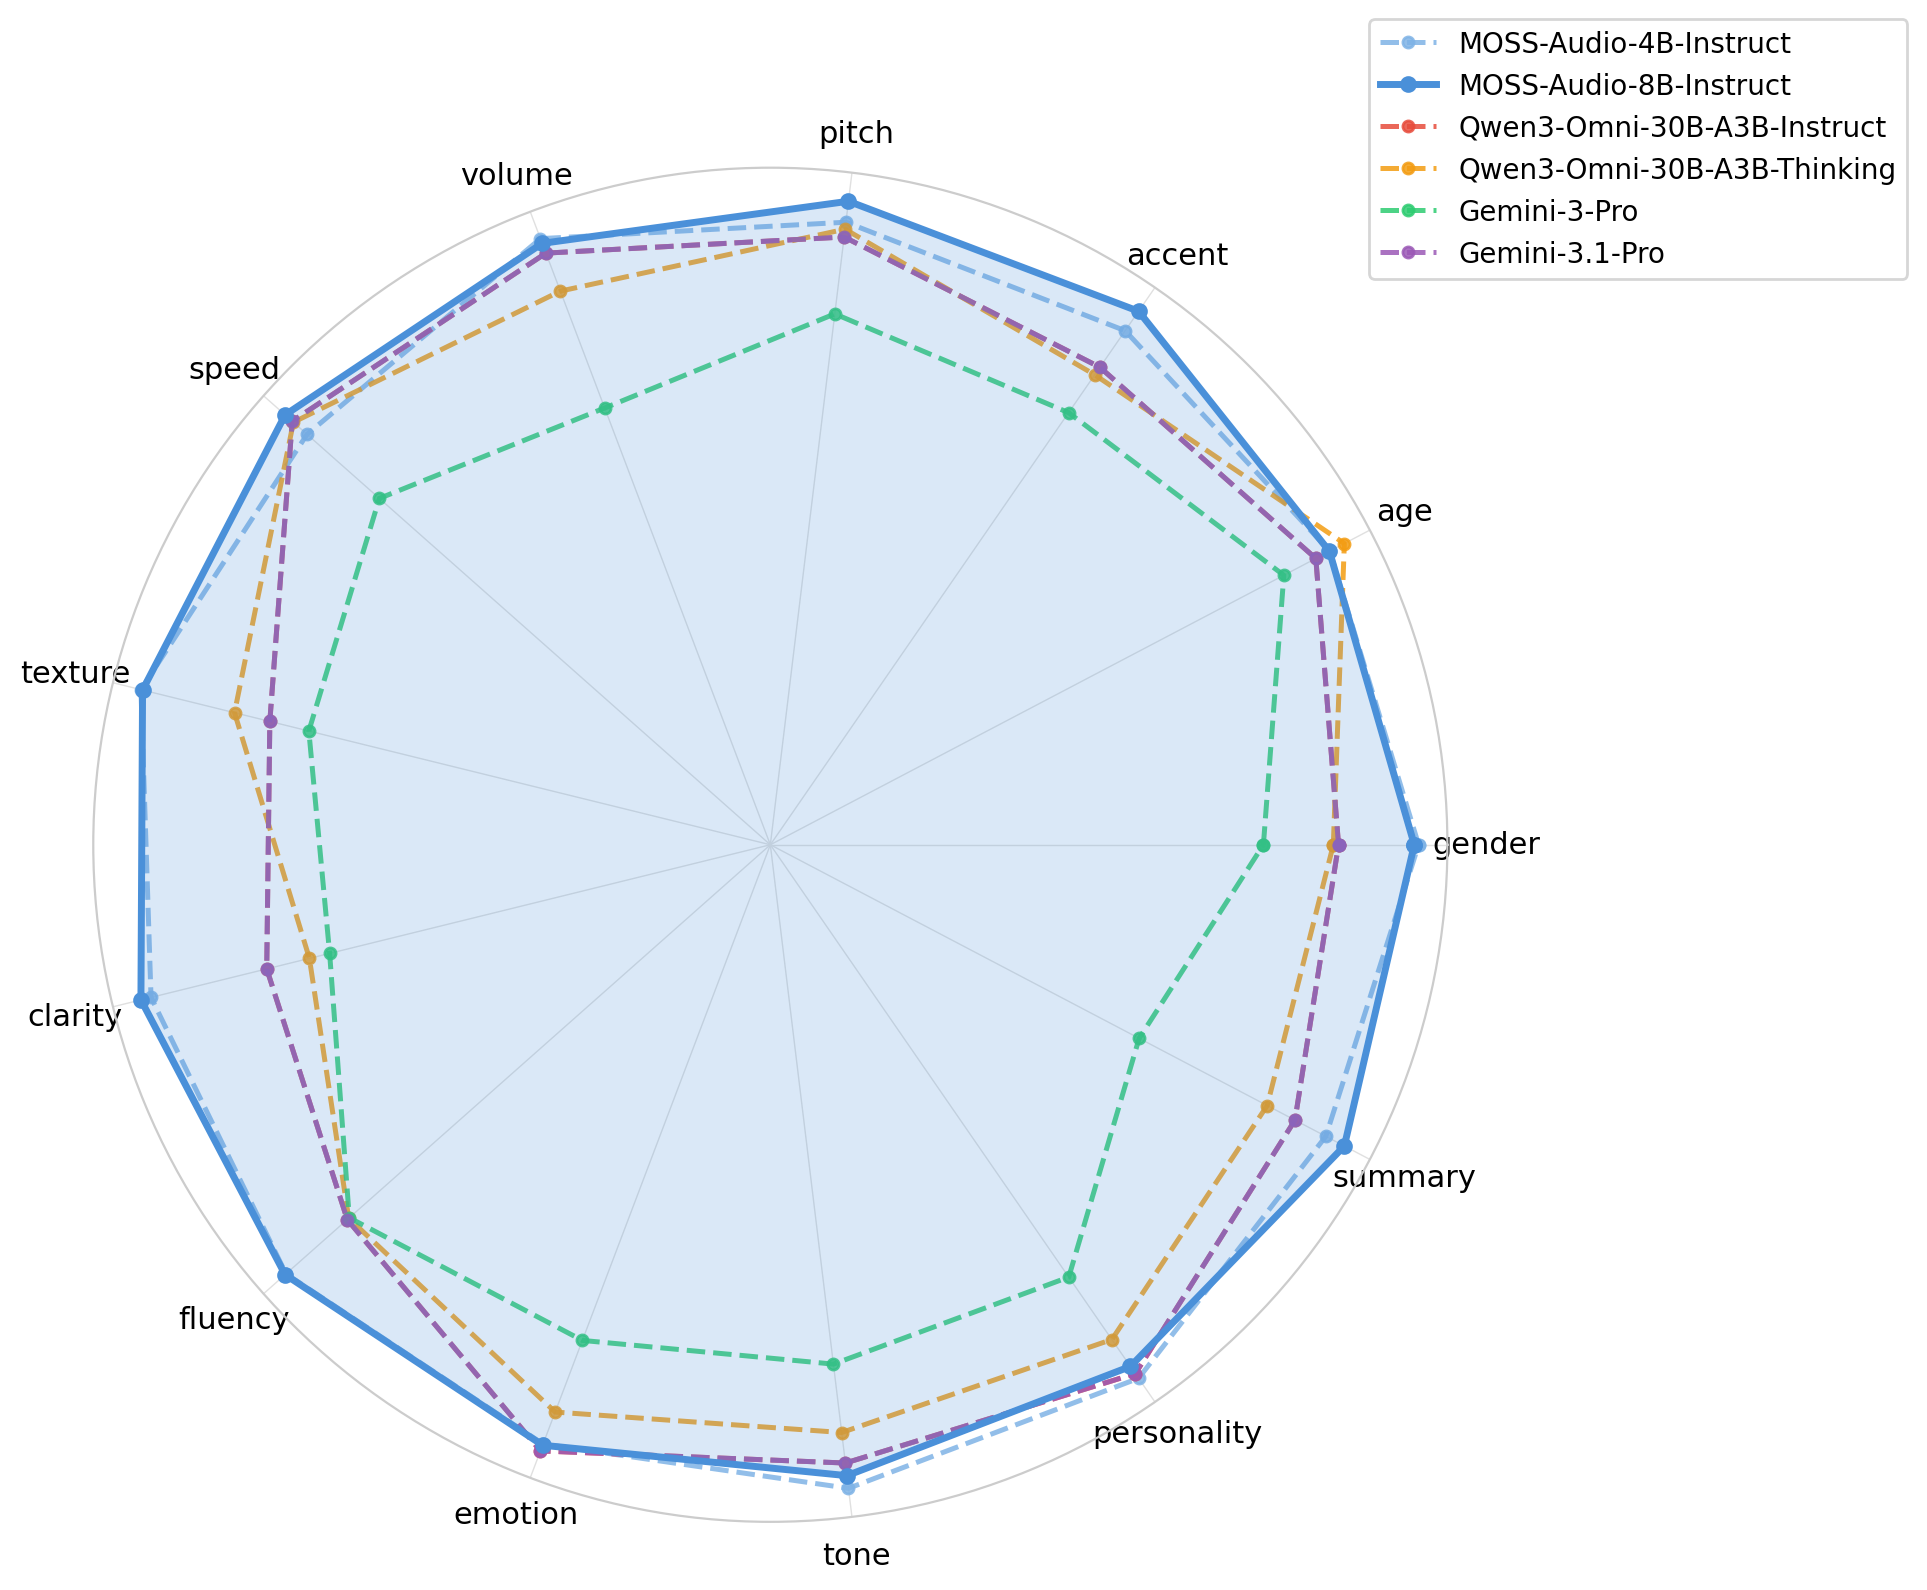
MOSS-Audio-8B-Instruct achieves the highest average score of 3.7252 on speech captioning tasks, leading in 11 of 13 fine-grained dimensions (gender, accent, pitch, volume, timbre, clarity, fluency, personality, etc.).
ASR Performance
MOSS-Audio-8B-Instruct leads with a comprehensive CER (character error rate) of 11.30. It stands out in the following challenging scenarios:
- Dialect recognition: CER 8.76 (91.24% accuracy)
- Singing transcription: CER 9.81
- Language switching: CER 10.18
- Non-speech vocalizations: CER 4.31
These results not only surpass traditional ASR models (Paraformer, Fun-ASR, SenseVoice) but are on par with larger multimodal models.
Timestamped ASR
MOSS-Audio's most eye-catching metric. Timestamped ASR measures the model's ability to transcribe audio while precisely annotating the timestamp of each word:
| Model | AISHELL-1 (Chinese) | LibriSpeech (English) |
|---|---|---|
| MOSS-Audio-8B-Instruct | 35.77 | 131.61 |
| MOSS-Audio-4B-Instruct | 76.96 | 358.13 |
| Qwen3-Omni-30B | 833.66 | 646.95 |
| Gemini-3.1-Pro | 708.24 | 871.19 |
MOSS-Audio-8B achieves 35.77 on AISHELL-1, far surpassing Qwen3-Omni-30B's 833.66 — a gap of over 23x. The advantage stems directly from the time-aware representation design: the model natively learns time alignment rather than relying on post-processing.
Core Capabilities
MOSS-Audio covers six core capabilities:
- Speech and Content Understanding — Precise transcription + word-level / sentence-level timestamp alignment
- Speaker / Emotion / Event Analysis — Identify speaker characteristics, analyze emotional states, detect key acoustic events
- Scene / Sound Cue Extraction — Infer context from background noise and environmental sounds
- Music Understanding — Analyze musical style, emotional progression, and instrument arrangement
- Audio QA and Summarization — Generate summaries and answer questions for podcasts, meetings, and interviews
- Complex Reasoning — Multi-hop reasoning via chain-of-thought
A single model covering all scenarios — developers no longer need to stitch together multiple specialized models for different audio tasks.
Deployment and Fine-Tuning
Environment Setup
git clone https://github.com/OpenMOSS/MOSS-Audio.git
cd MOSS-Audio
conda create -n moss-audio python=3.12 -y
conda activate moss-audio
conda install -c conda-forge "ffmpeg=7" -y
pip install --extra-index-url https://download.pytorch.org/whl/cu128 -e ".[torch-runtime]"
Inference
python infer.py # Default prompt: Describe this audio.
Gradio UI
python app.py
SGLang Service Deployment
git clone -b moss-audio https://github.com/OpenMOSS/sglang.git
cd sglang && pip install -e "python[all]"
sglang serve --model-path ./weights/MOSS-Audio --trust-remote-code
Fine-Tuning
Official fine-tuning scripts are provided (finetune/finetune.py), supporting both LoRA and full-parameter fine-tuning. The data format is JSONL audio-text conversation pairs.
Technical Deep Dive
Why Can 8B Challenge 30B?
MOSS-Audio's efficiency advantage comes from three layers.
Audio encoding efficiency. The self-trained encoder is optimized for 12.5 Hz time resolution. Compared to general-purpose encoders (e.g., Wav2Vec2's 50 Hz output), sequence length is compressed roughly 4x, significantly reducing LLM input token count.
Information density from cross-layer injection. The DeepStack design allows the LLM to receive multi-level features simultaneously, avoiding the need for the LLM to "learn from scratch" at low-level acoustic features. It's equivalent to providing the LLM with preprocessed acoustic knowledge rather than raw encoded representations.
Native time-aware integration. Time-marker tokens are embedded in the sequence during pre-training. Time-aware capabilities are encoded into model weights with no additional inference overhead.
Why the Massive Gap in Timestamped ASR?
Competitors' weak performance on timestamped ASR stems fundamentally from architecture design. Models like Qwen3-Omni rely on post-processing modules or additional localization heads to generate timestamps, essentially treating time alignment as a separate task. MOSS-Audio embeds time markers in the sequence during pre-training, making time awareness a core capability rather than an add-on feature.
This is analogous to the gap between models natively multilingual versus models that understand languages post-translation — the former builds mappings at a lower level, while the latter requires an additional conversion layer.
Apache 2.0 License
MOSS-Audio is released under the Apache License 2.0, allowing commercial use, modification, and distribution without copyleft restrictions.
Final Thoughts
The release of MOSS-Audio marks an important advancement in the open-source audio understanding landscape. Achieving performance that surpasses 30B models at 8B parameter scale, with orders-of-magnitude advantages in timestamped ASR, demonstrates the core value of architectural innovation. The two key innovations — DeepStack cross-layer injection and time-aware representation — provide a reference for audio-language model design.
With improved fine-tuning support and service deployment tools, MOSS-Audio now offers a complete pipeline from research to production.
Related Links
- HuggingFace: https://huggingface.co/collections/OpenMOSS-Team/moss-audio
- GitHub: https://github.com/OpenMOSS/MOSS-Audio
- OpenMOSS Official Site: https://www.open-moss.com/