Baidu's Open-Source ERNIE-Image-Turbo 8B: The Most Comprehensive Multi-Model Horizontal Comparison
Baidu just open-sourced ERNIE-Image, an 8B-parameter text-to-image model. When comparing text-to-image models, we can't help but compare parameter counts. Parameter count doesn't directly show a model's capabilities or strengths, but we still believe that "bigger is generally better." However, parameter count is just potential — real capability depends on training quality. We won't make subjective judgments; we'll leave it all to the benchmarks.
First, let's list the open-source text-to-image models available as of today, ranked by parameter count.
Open-Source Text-to-Image Model Parameter Rankings
HunyuanImage-3.0 (Tencent Hunyuan) — 80B total parameters (MoE, 64 experts, ~13B active)
- Currently the largest open-source T2I MoE model, native multimodal autoregressive architecture, excels at complex prompts, world knowledge reasoning, Chinese/English text rendering, and knowledge-dense generation. Suitable for high-quality, professional scenarios, but requires high-end hardware for inference (datacenter-grade, optimizable with quantization). Open-sourced September 2025, weights available on HF.
FLUX.2 [dev] (Black Forest Labs) — 32B parameters
- Open-source version of FLUX.2 series, supporting T2I, image editing, and multi-reference image fusion. Rectified flow transformer architecture with extremely strong prompt following, detail, and coherence. Runs on consumer GPUs (with quantization/FP8 optimization), one of the 2026 open-source flagship models.
FLUX.1 [dev/schnell] — ~12B parameters
- (Early FLUX.1 series, Kontext Pro at ~12B) Classic DiT/flow matching model with top-tier prompt following and text rendering. Schnell is the distilled fast version. Largest community ecosystem, well-supported by ComfyUI.
Stable Diffusion 3.5 Large (Stability AI) — 8.1B parameters (MMDiT)
- SD series' latest flagship, significantly improved prompt following and typography, supports 1MP+ resolution. Medium variant at 2.5B parameters, more suitable for consumer hardware. Largest open-source community, mature LoRA/fine-tuning ecosystem.
Qwen-Image / Qwen-Image-2.0 (Alibaba Qwen) — ~7B–20B parameters
- (2.0 unified at ~7B, lightweight and efficient) Strong Chinese/multilingual text rendering, professional typography (supports 1K token long prompts), native 2K resolution. Version 2.0 unified generation + editing, high efficiency, ideal for Asian languages and infographics.
Z-Image-Turbo / Other small efficient models — ~6B parameters
- Efficient real-time/edge deployment models, fast speed, suitable for low-resource environments.
So in terms of parameter count, Baidu's ERNIE-Image is actually not that large — it sits in the middle. As for visual performance, let the images speak.
ERNIE-Image Introduction
ERNIE-Image is an open text-to-image model developed by Baidu's ERNIE-Image team. Based on a single-stream Diffusion Transformer (DiT) with 8B parameters, it uses a Latent Diffusion Model (LDM) framework equipped with a lightweight Prompt Enhancer that expands short inputs into richer, more structured prompts to better unlock model capabilities. With just 8B DiT parameters, ERNIE-Image achieves state-of-the-art performance among open-weight text-to-image models — it cares not only about visual appeal but also controllability: accurate content representation is as important as aesthetics. In practice, it excels at complex instruction following, precise text rendering, and structured image generation — areas where many existing open-weight models still fall short.
Model Benchmark Horizontal Comparison (Official)
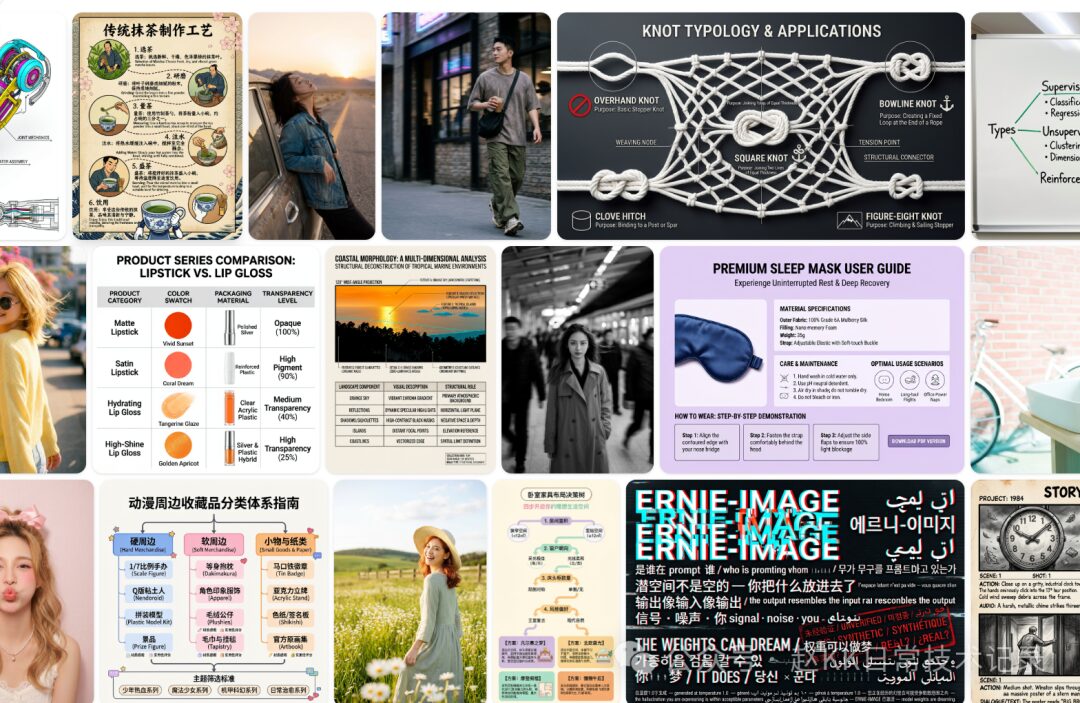
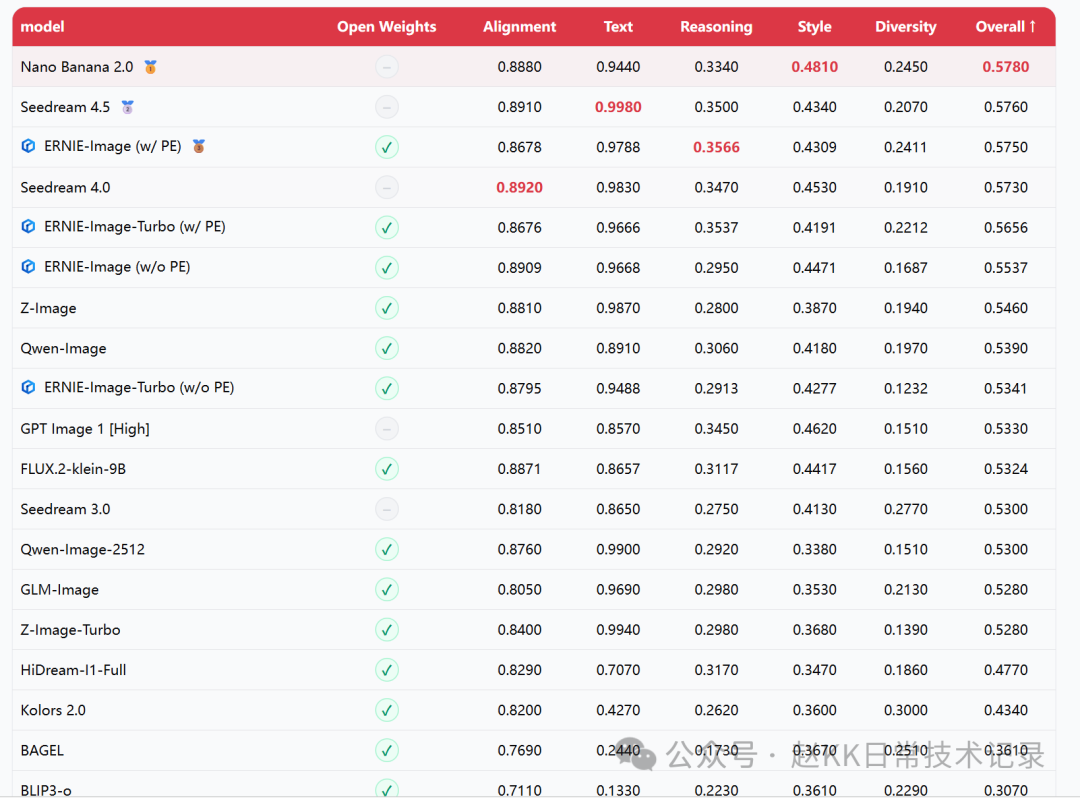
Built-in Prompt Enhancement
ERNIE-Image performs best with verbose, detailed, and well-structured prompts — richer descriptions generally bring better generation quality, tighter instruction fidelity, and more faithful reproduction of complex layouts or narrative content. But in reality, users typically input short sentences rather than detailed prompts that leverage the model's strengths.
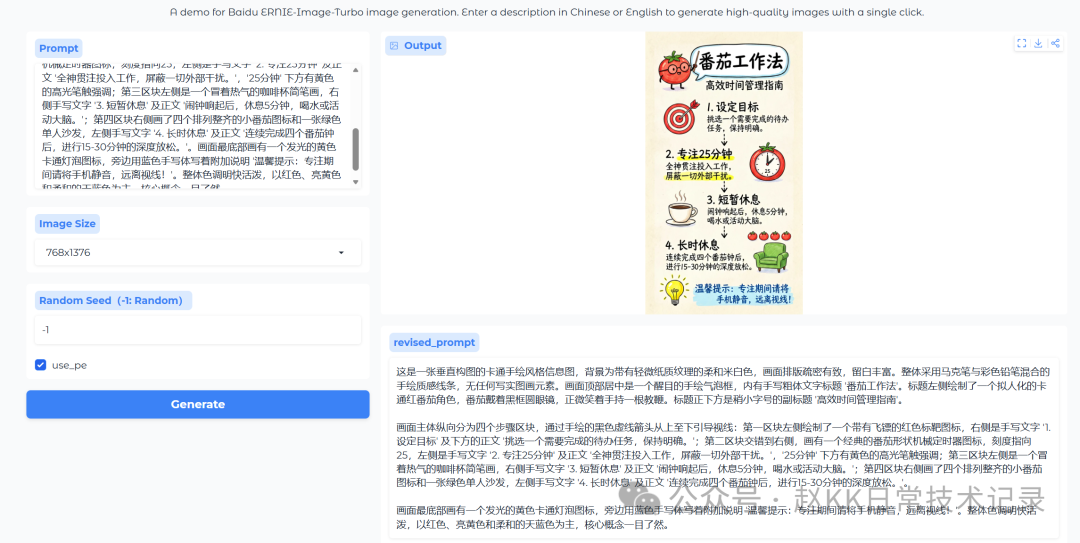
To bridge this gap, we released a built-in 3B Prompt Enhancer that expands short user inputs into more detailed, structured prompts better suited for ERNIE-Image. The goal is not to change the user's intent, but to transform concise requests into a form that better unlocks the model's value — especially in posters, anime, web layouts, game screenshots, and other structured visual tasks.
The examples below illustrate this effect. Without prompt enhancement, the model tends to interpret short prompts literally and incompletely. With our 3B Prompt Enhancer, prompts become more descriptive and structured, significantly improving results in many scenarios. We also found that stronger LLMs can push this goal further — suggesting that prompt enhancement is a practical lever for leveraging ERNIE-Image's long-prompt generation capabilities.
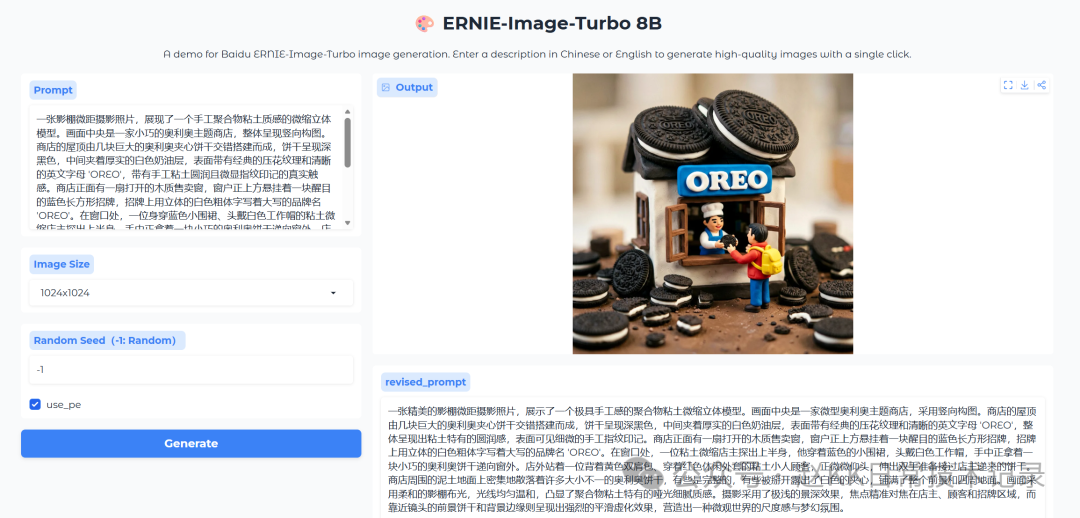
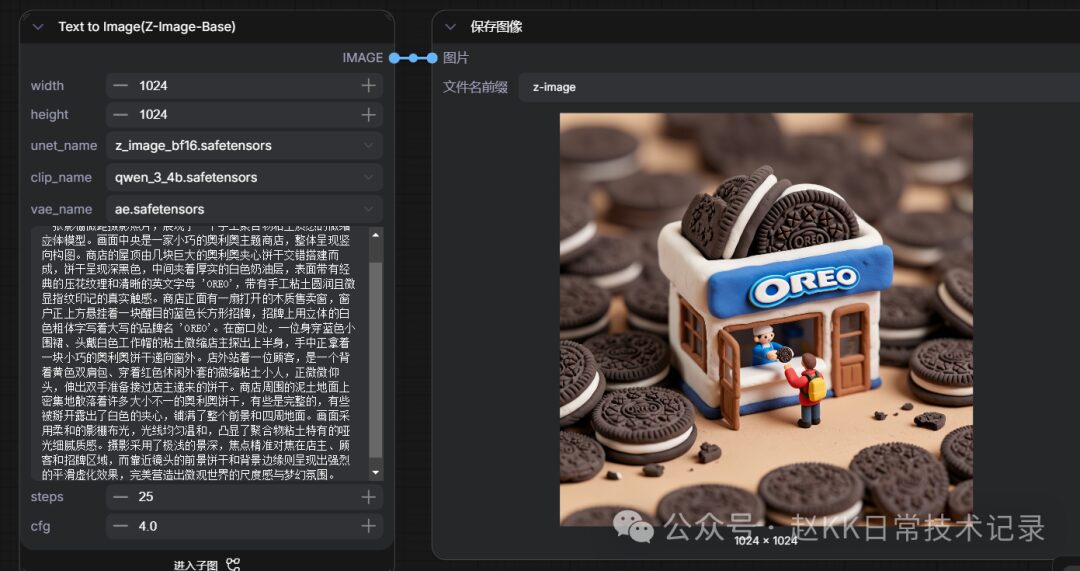
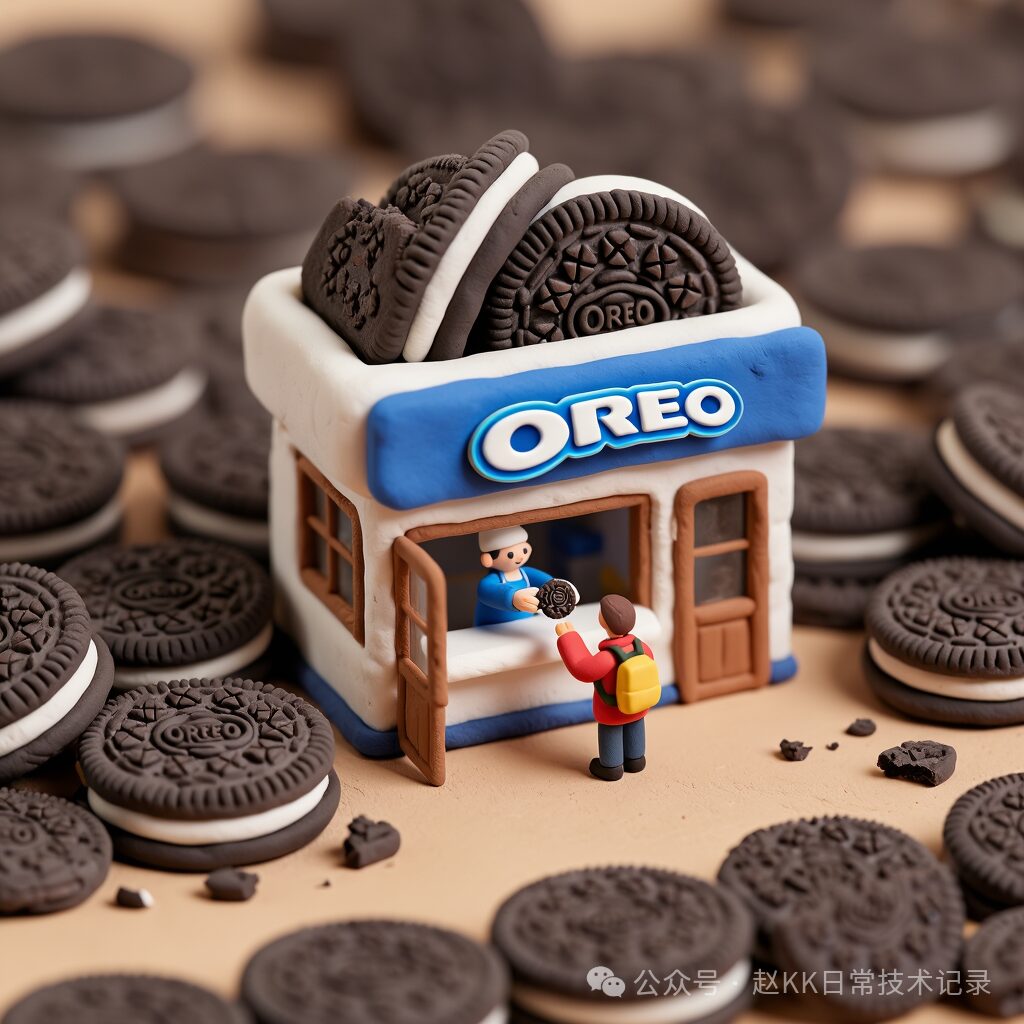
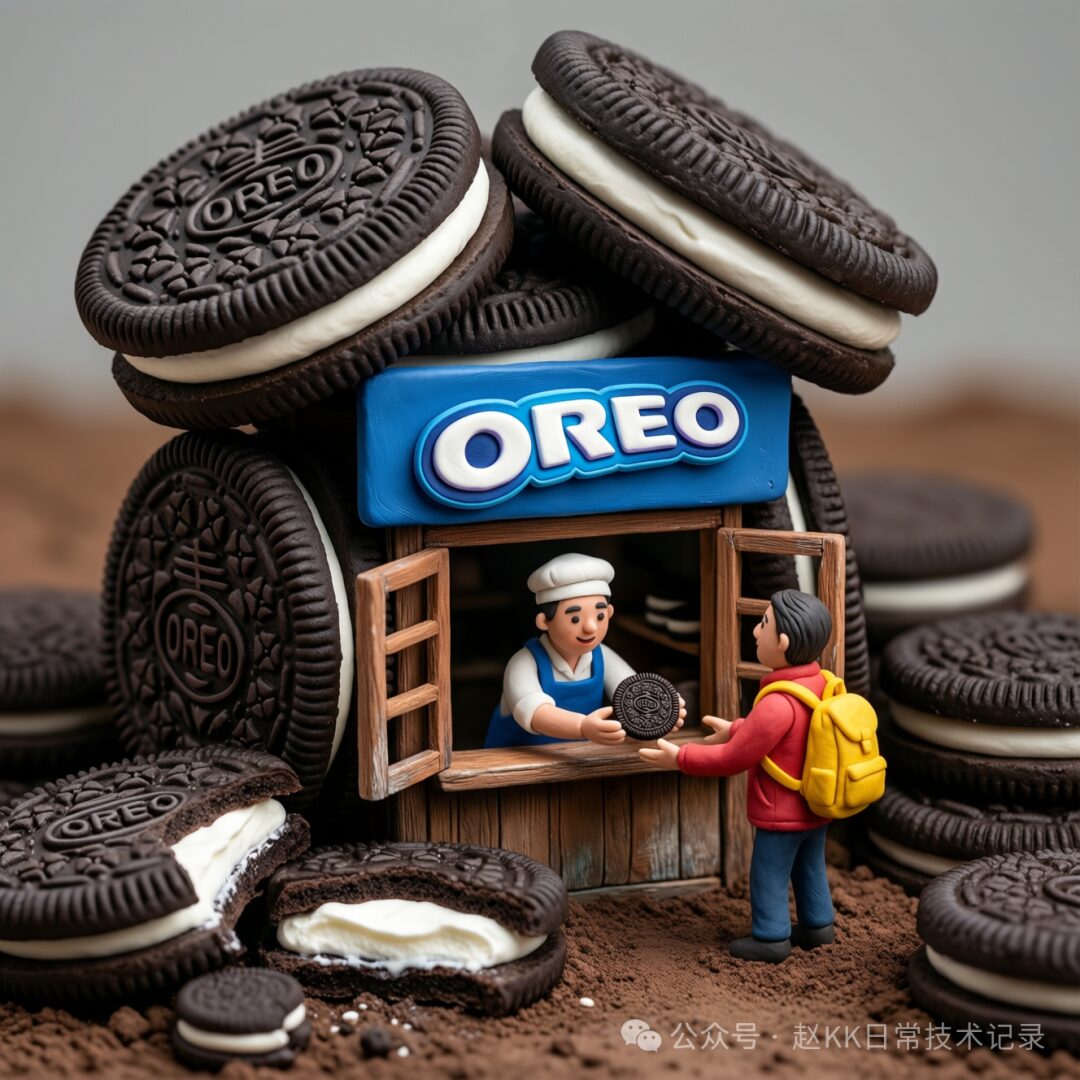
Official Prompt Reproduction Test
For fairness, we reproduced results using the official prompts from the online demo at https://huggingface.co/spaces/baidu/ERNIE-Image-Turbo
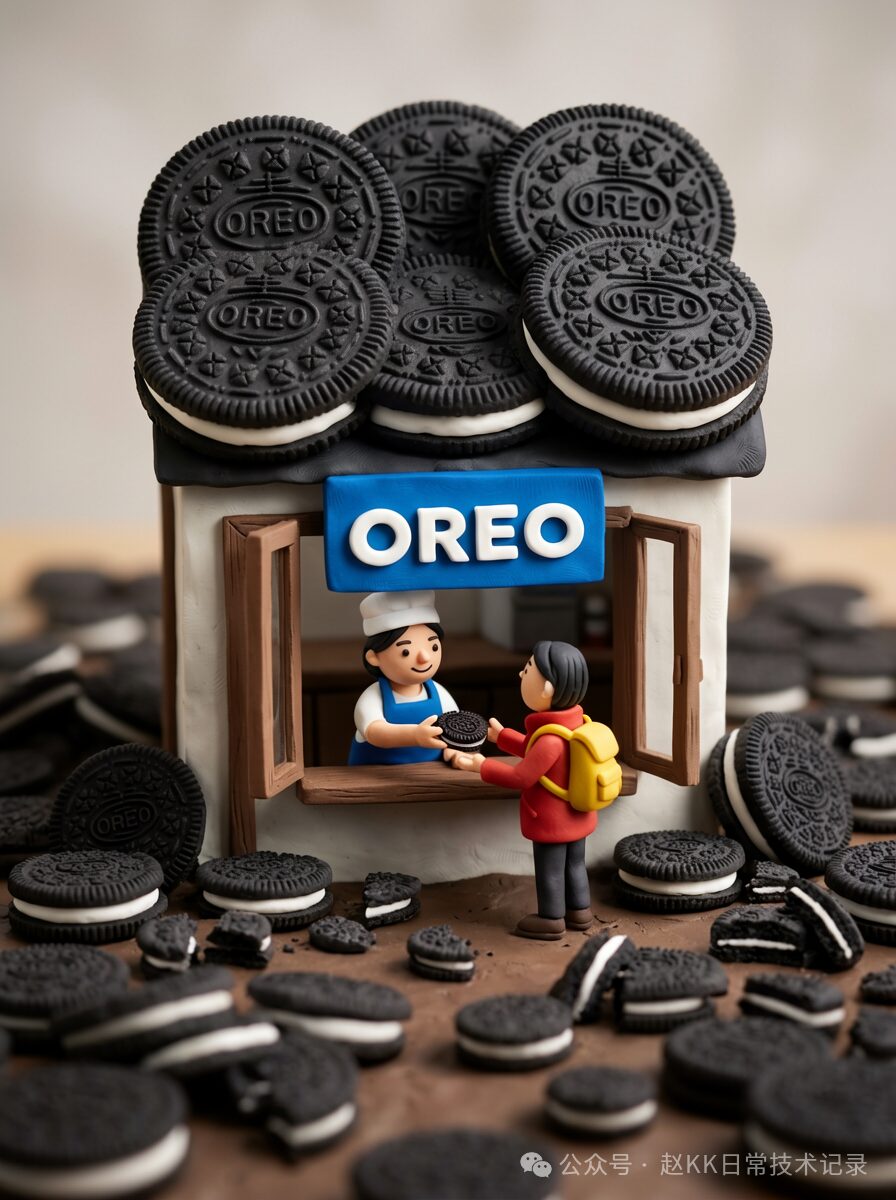
Prompt (Oreo Miniature Scene)
This prompt is quite complex:
A studio macro photograph showcasing a handcrafted polymer clay-textured miniature diorama. Centered vertically is a small Oreo-themed shop. The roof is constructed from oversized Oreo cookie pieces interlocked together — dark black with thick white cream filling, classic embossed texture, and clear 'OREO' lettering with handmade clay roundness and subtle fingerprint marks for realistic tactile feel. The shop front has an open wooden serving window with a prominent blue rectangular signboard above it displaying the brand name 'OREO' in bold 3D white letters. At the window, a miniature clay shopkeeper wearing a blue apron and white work cap leans forward, holding a small Oreo cookie outward. Outside stands a customer — a miniature clay figure with a yellow backpack and red casual jacket, looking up slightly with both hands extended to receive the cookie. The ground around the shop is densely scattered with Oreos of various sizes — some whole, some broken revealing white filling — covering the entire foreground and surrounding ground. Soft studio lighting, even and gentle, highlighting the polymer clay's characteristic semi-gloss texture. Extremely shallow depth of field, precise focus on the shopkeeper, customer, and sign area, while foreground cookies and background edges show strong smooth blur, perfectly creating the miniature world's scale and dreamy atmosphere.
Official Result
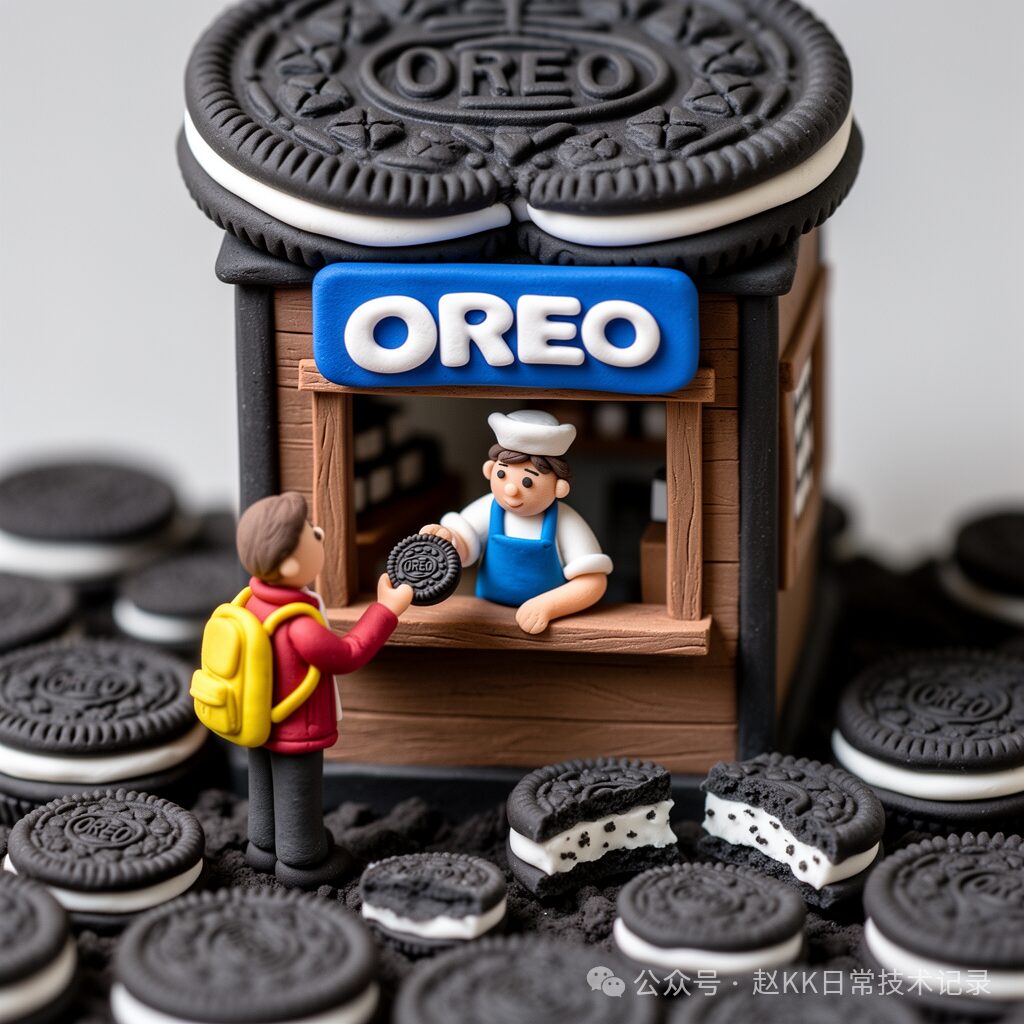
Baidu ERNIE-Image Reproduction
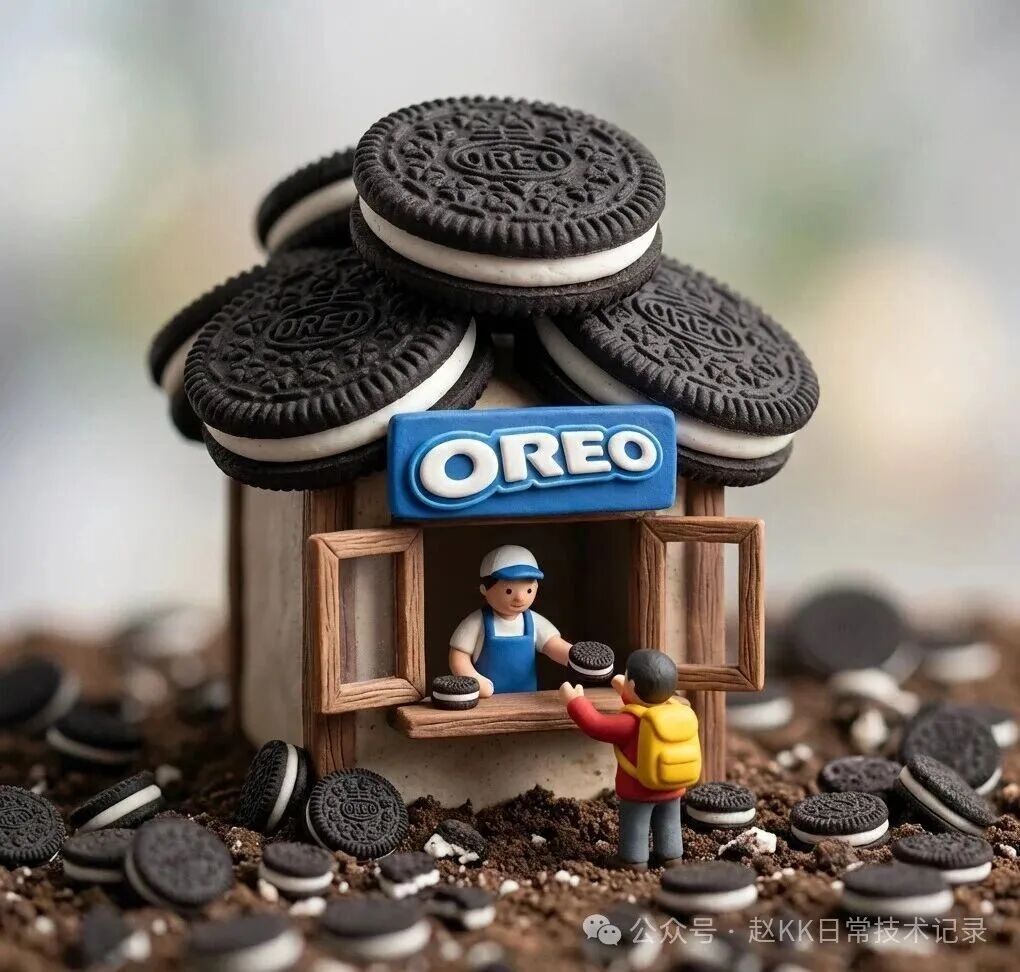
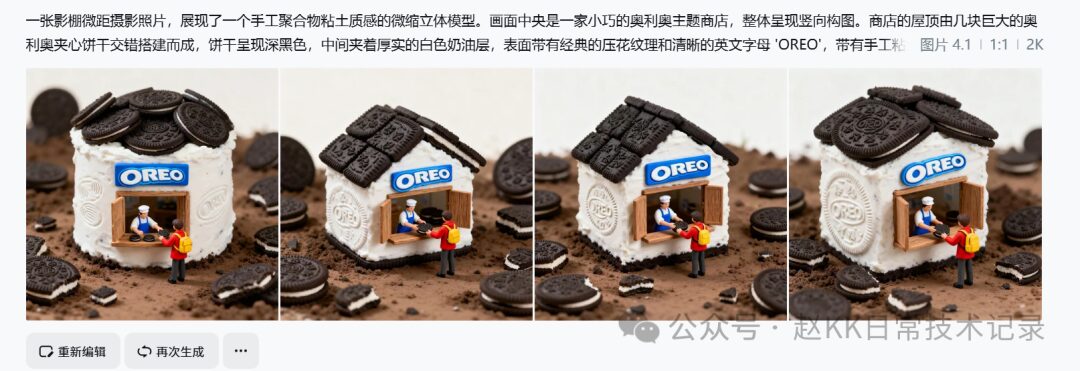
Z-Image
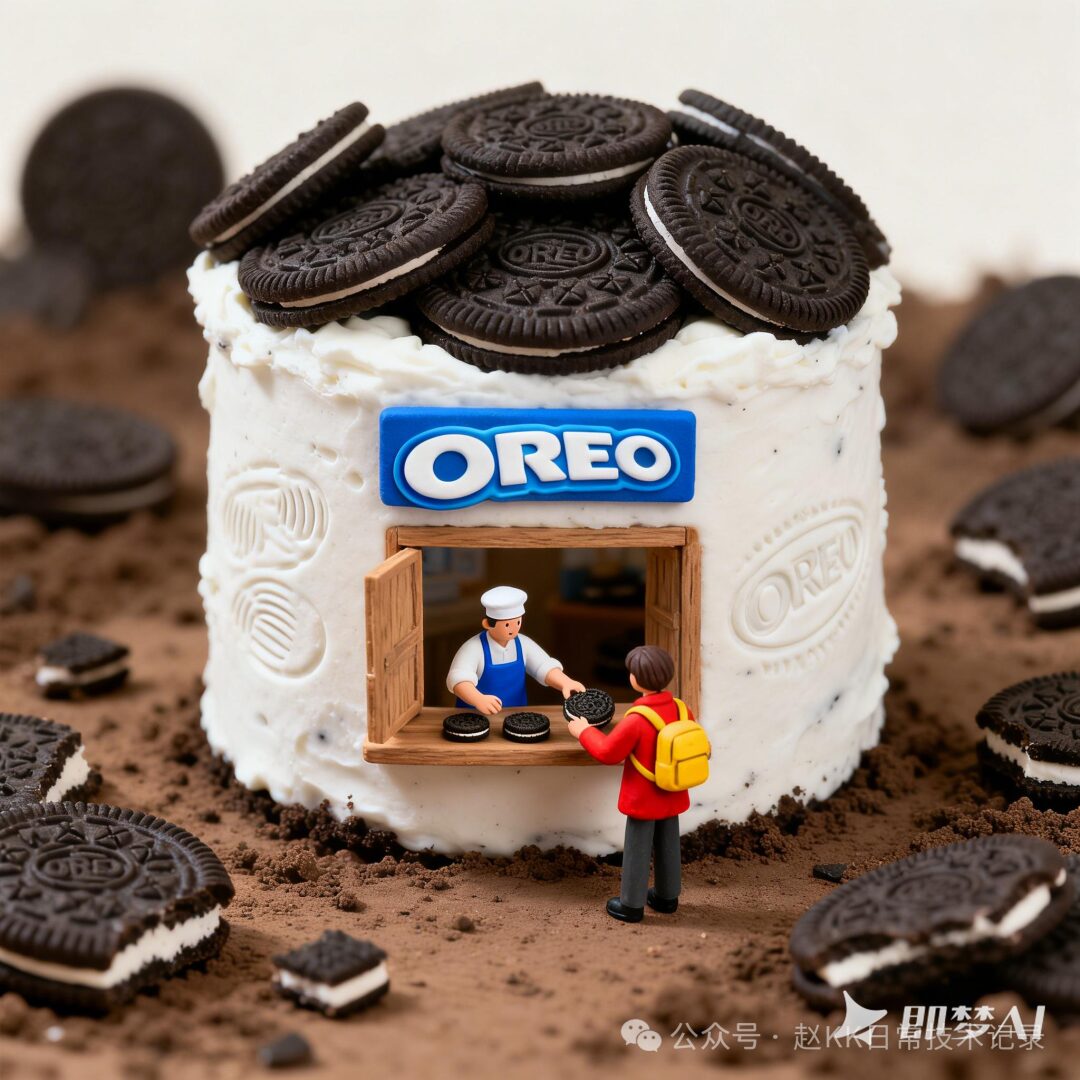
FireRed Qwen-Image-2512
Flux2
Nanobana 2 pro
Jimeng (即梦)
Multi-Text Combination Test
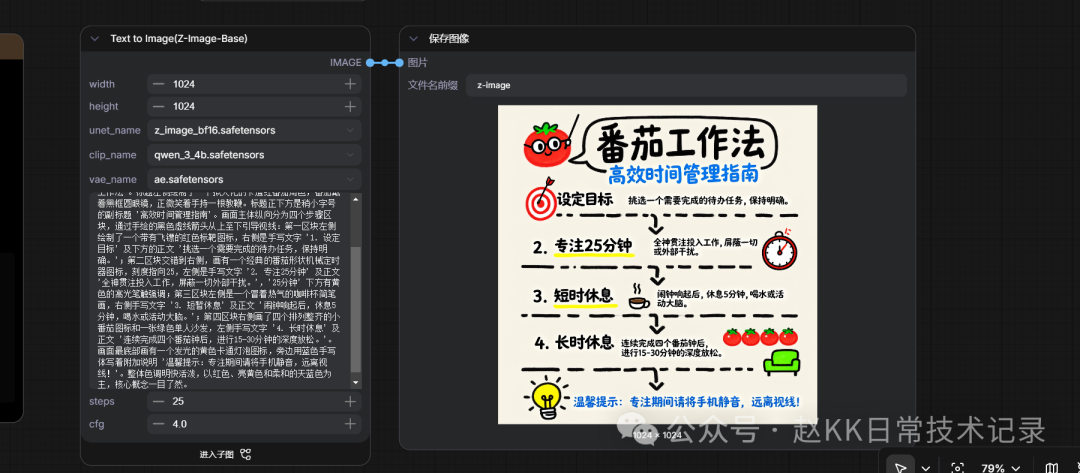
Chinese text can be 100% reproduced by Z-image
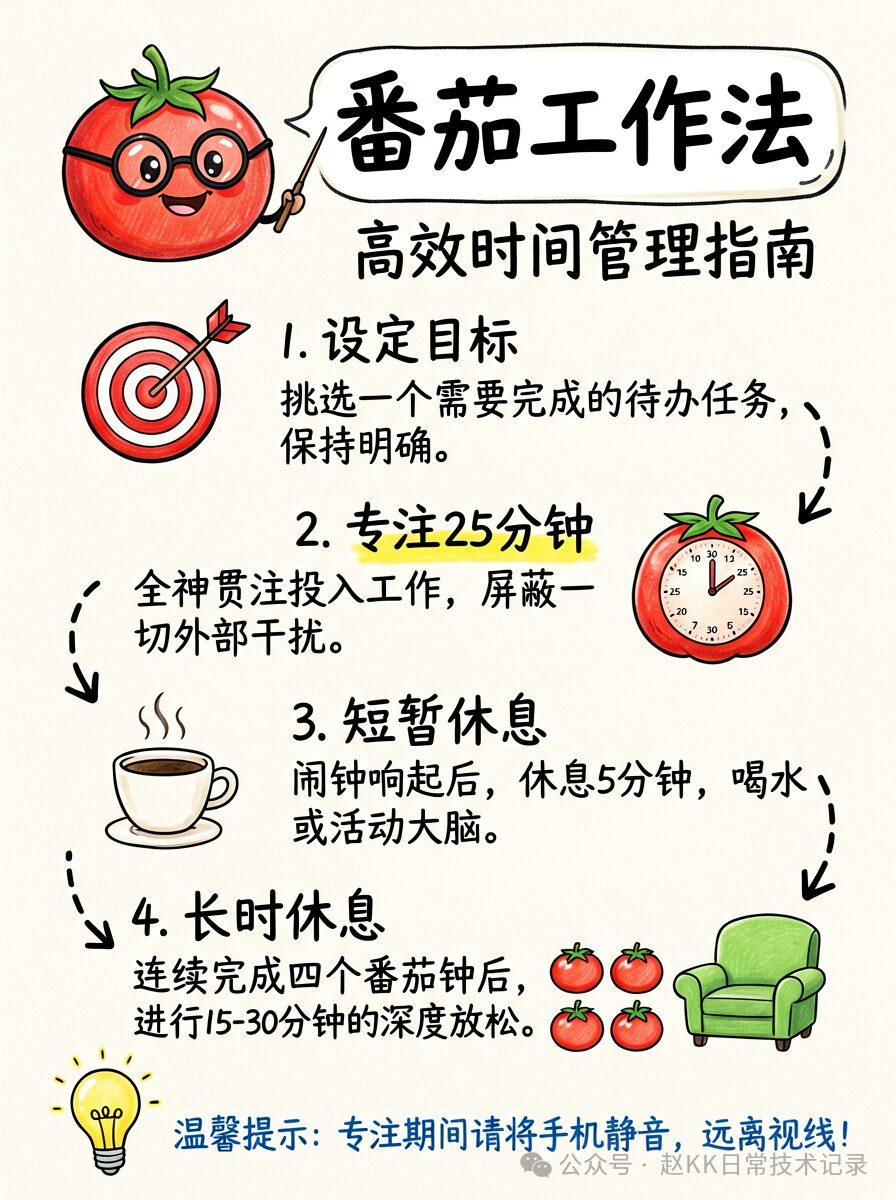
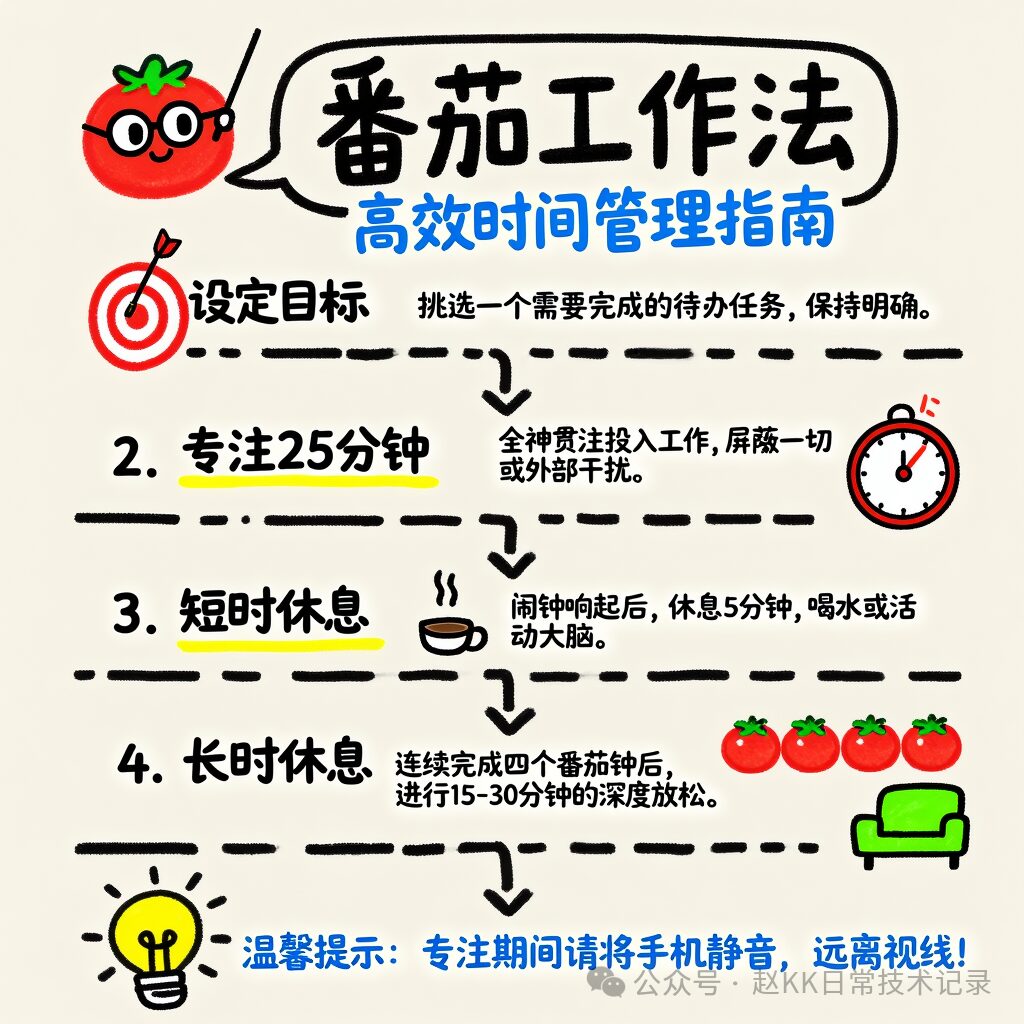
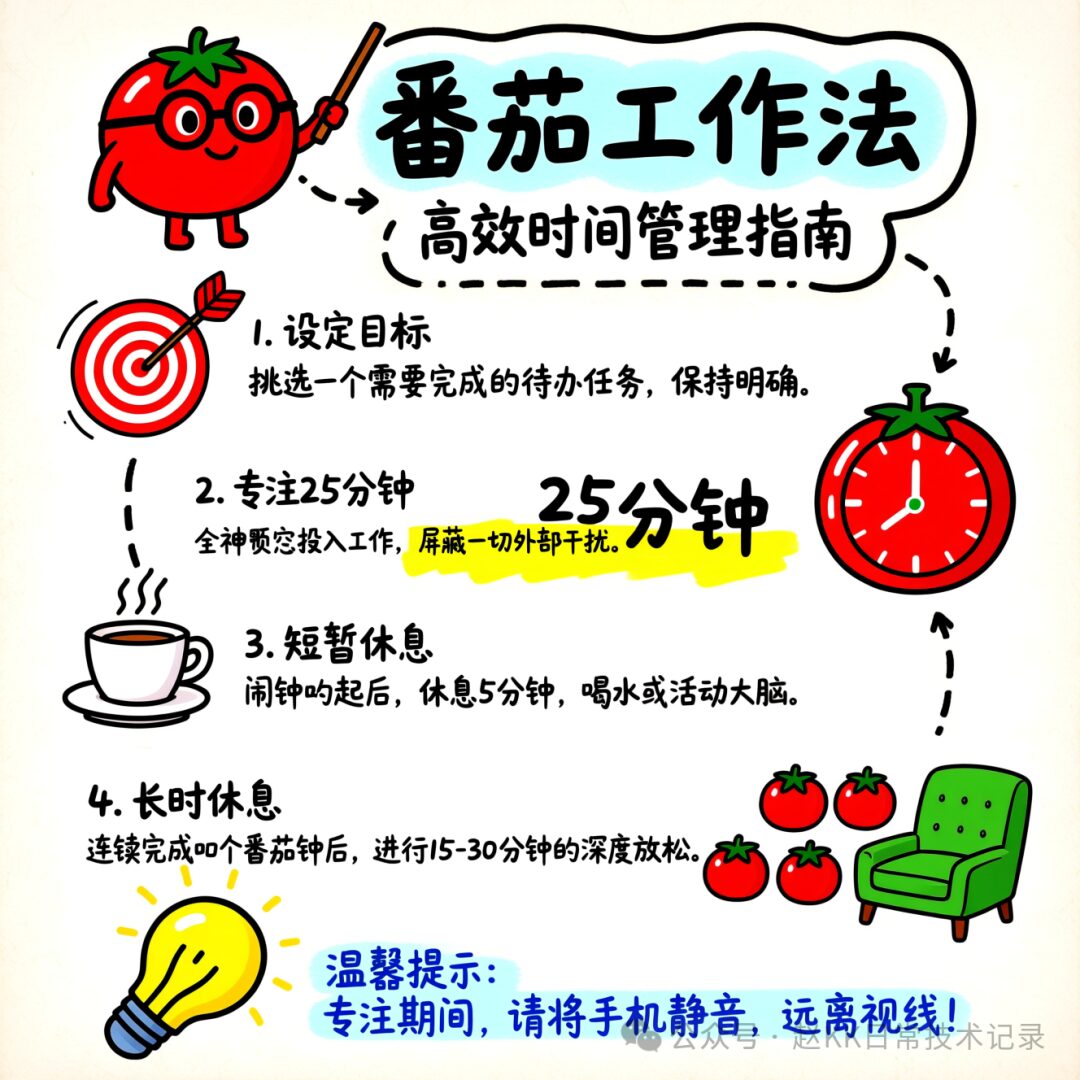
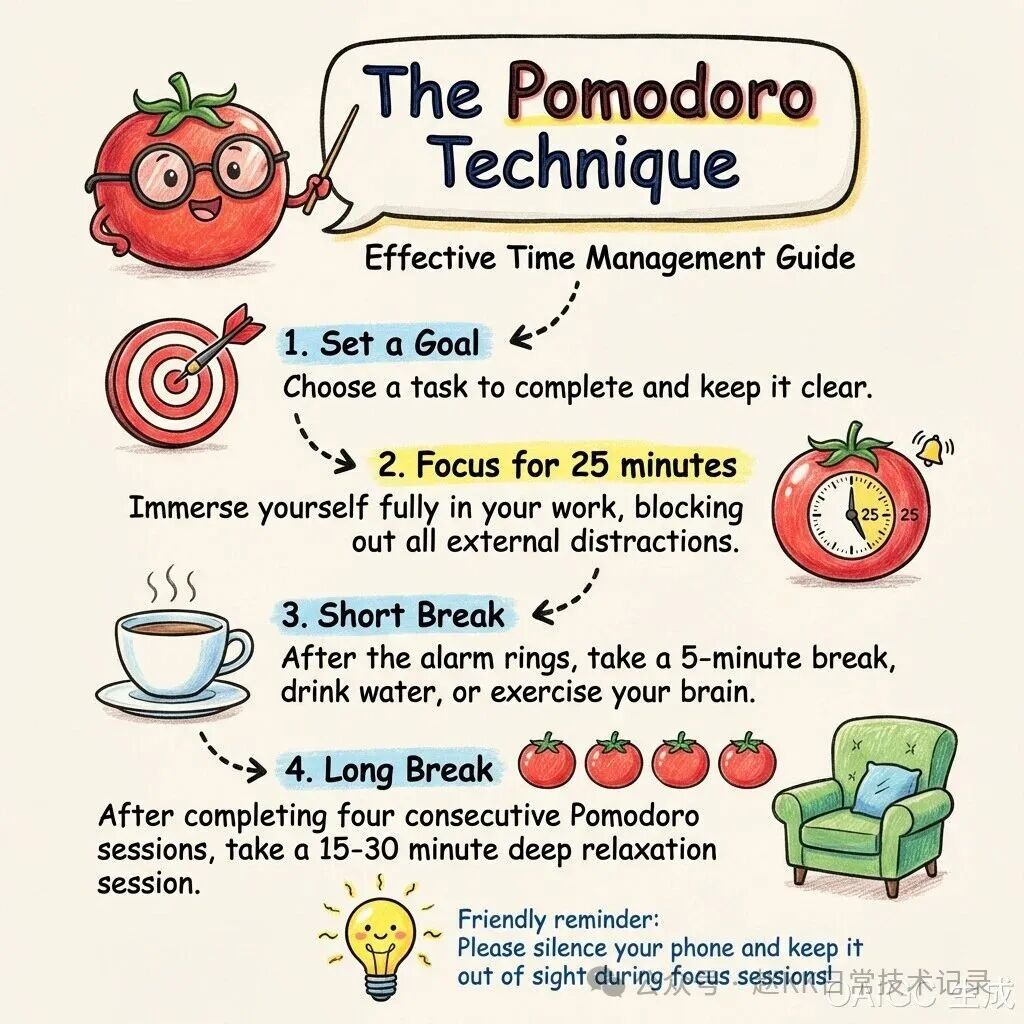
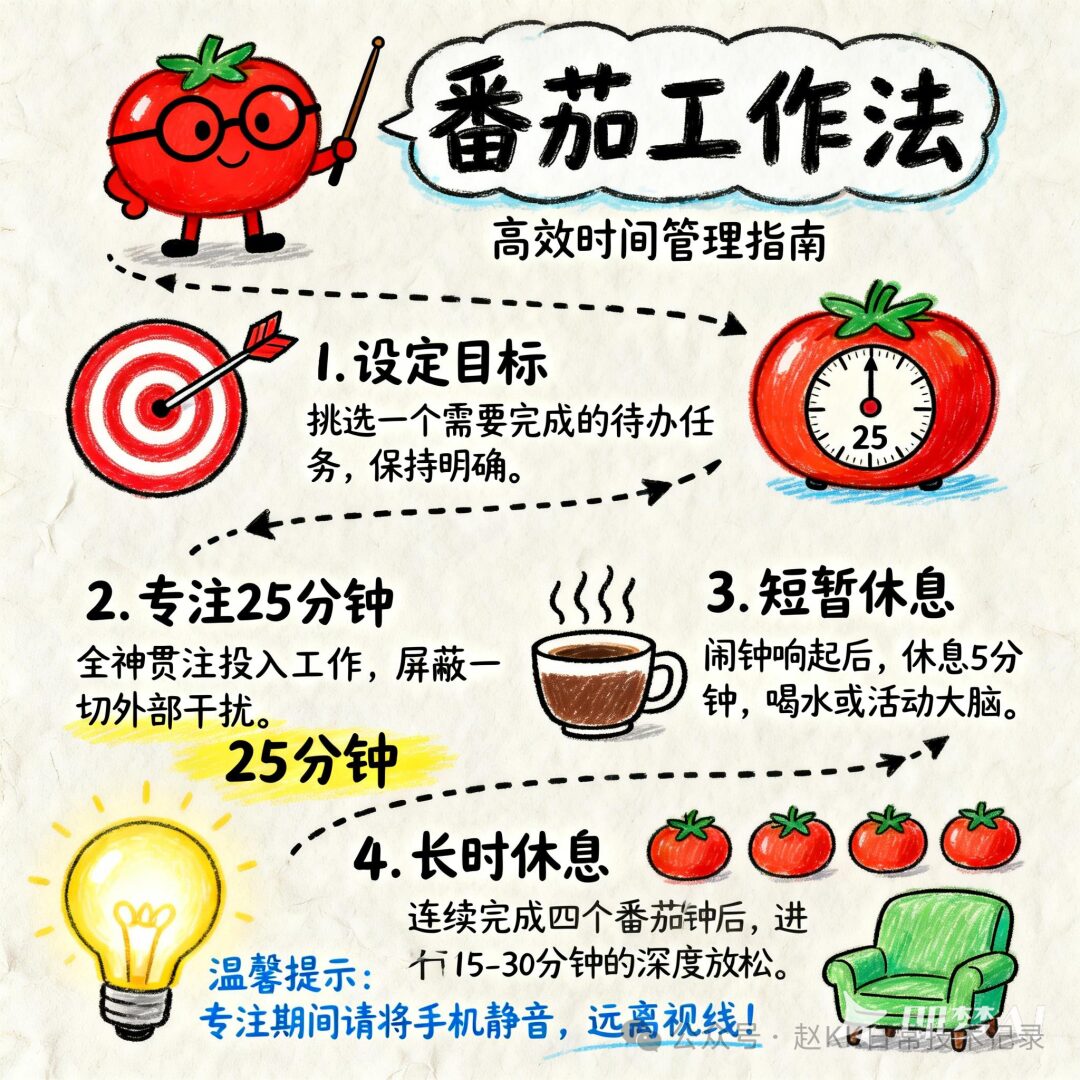
Prompt (Pomodoro Technique Infographic)
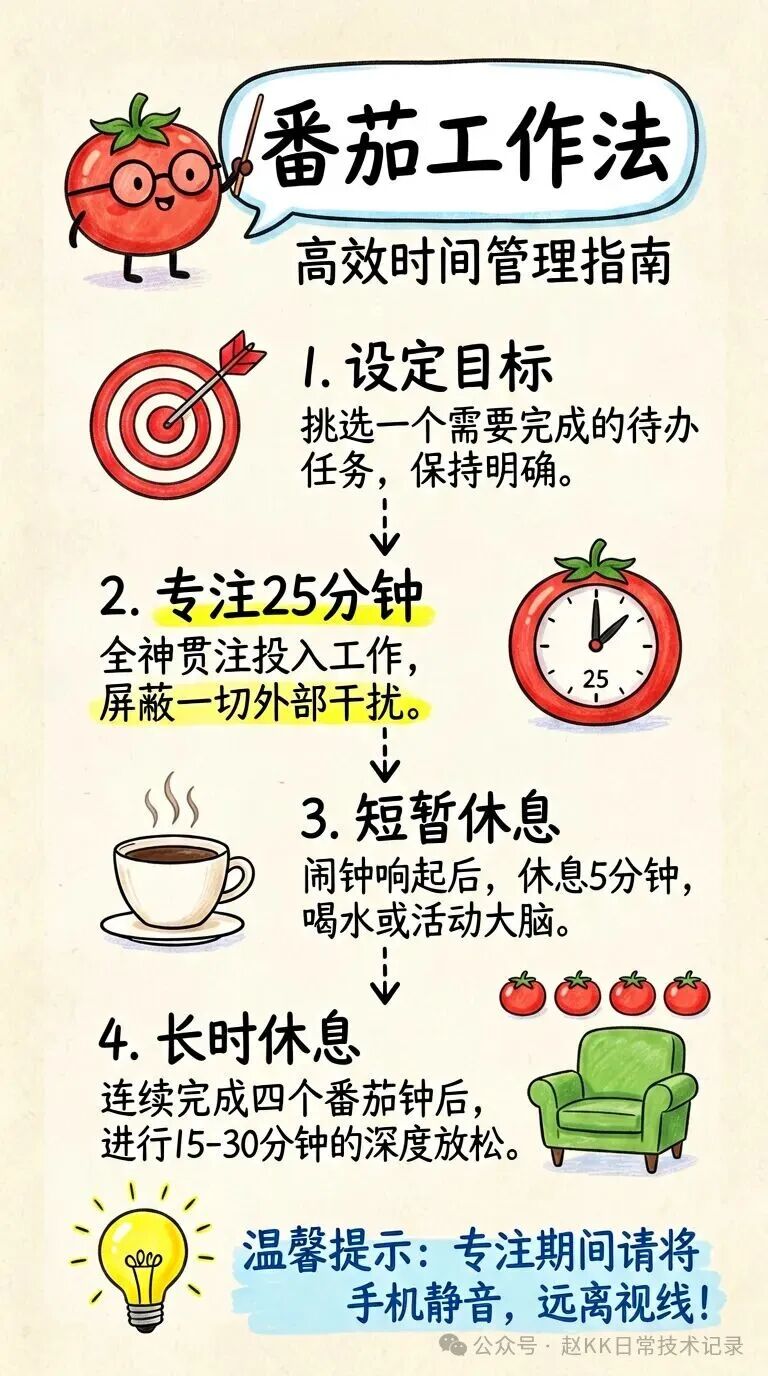
A vertical-layout cartoon hand-drawn style infographic, soft off-white background with slight paper texture, well-organized layout with generous white space. Markers and colored pencil hand-drawn textured lines throughout, no photorealistic elements. Top center is a prominent hand-drawn bubble frame with handwritten bold title text '番茄工作法' (Pomodoro Technique). To the left of the title is an anthropomorphic cartoon red tomato character wearing round black-framed glasses, smiling and holding a pointer. Below the title is a smaller subtitle '高效时间管理指南' (Efficient Time Management Guide). The main body is vertically divided into four step sections, guided by hand-drawn dashed black arrows from top to bottom: Section 1 left side has a red target icon with a dart, right side has handwritten text '1. 设定目标' (Set Goals) with body text '挑出一个需要完成的待办任务,保持明确。' (Pick one task to complete, keep it clear.); Section 2 alternates to the right with a classic tomato-shaped mechanical timer icon showing 25, left side has '2. 专注25分钟' (Focus for 25 minutes) with body text '全神贯注投入工作,屏蔽一切外部干扰。' (Focus fully on work, block all distractions.), with yellow highlight emphasis below '25分钟'; Section 3 left side has a steaming coffee cup sketch, right side '3. 短暂休息' (Short Break) with '闹钟响起后,休息5分钟,喝水或活动大脑。' (After the alarm, rest 5 minutes, drink water or stretch.); Section 4 right side has four neatly arranged small tomato icons and a green armchair, left side '4. 长时休息' (Long Break) with '连续完成四个番茄钟后,进行15-30分钟的深度放松。' (After four Pomodoro cycles, take 15-30 minutes of deep relaxation.). Bottom has a glowing yellow cartoon lightbulb icon with blue handwritten note '温馨提示:专注期间请将手机静音,远离视线!' (Reminder: mute your phone during focus, keep it out of sight!). Overall bright and lively color scheme dominated by red, bright yellow, and soft sky blue, with core concepts at a glance.
Official Result
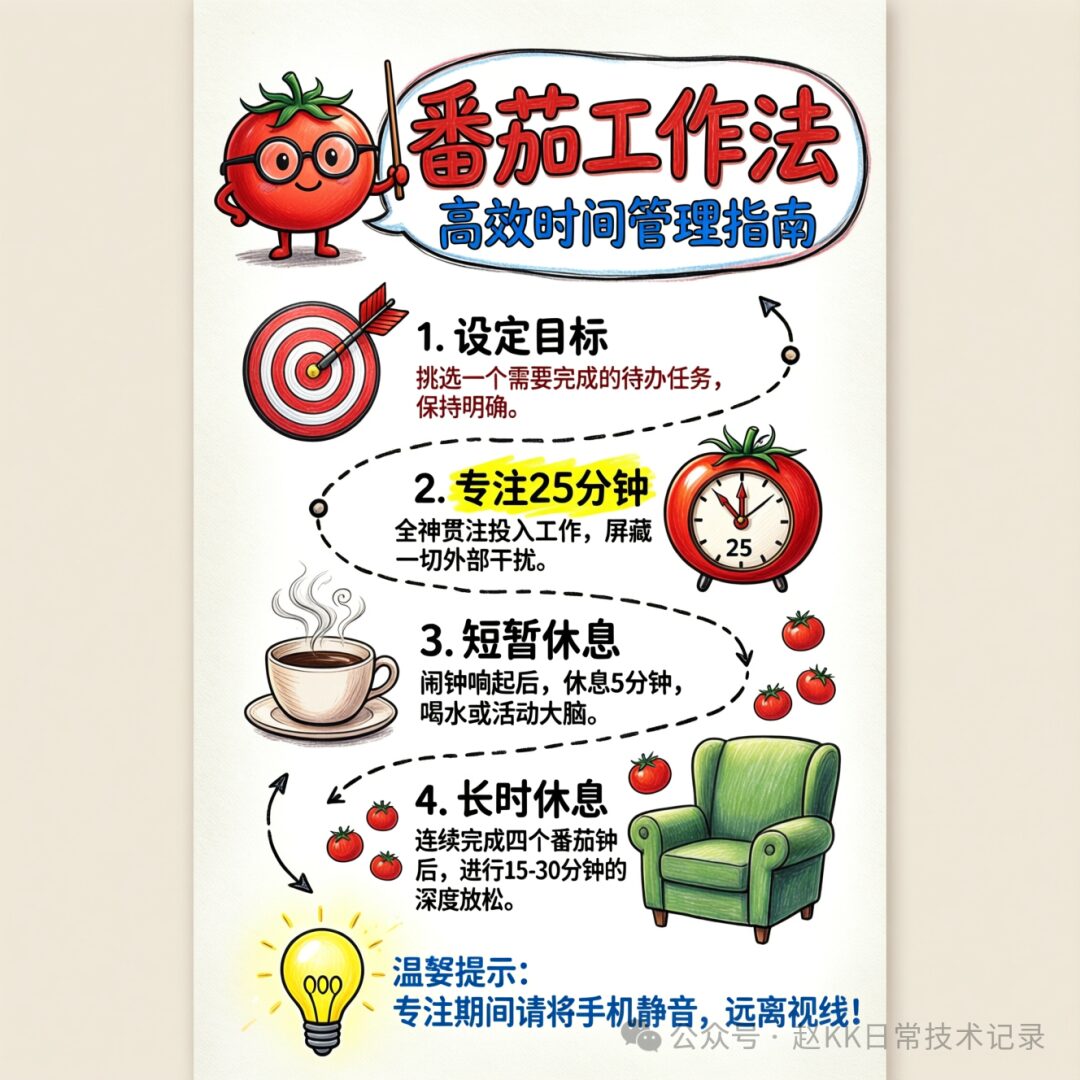
Baidu ERNIE-Image Reproduction
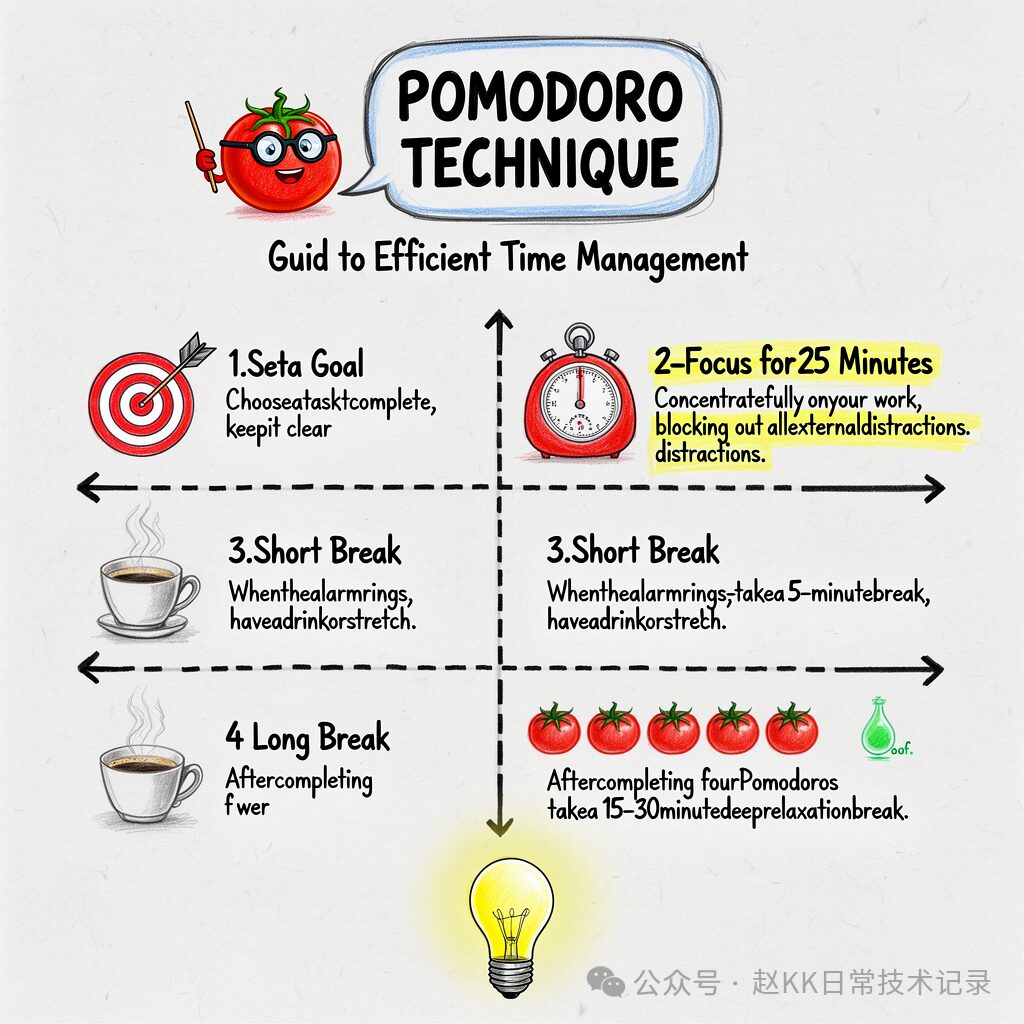
Z-Image
FireRed Qwen-Image-2512
Flux2
Nanobana 2 pro (poor Chinese support, result in English)
Jimeng (即梦)
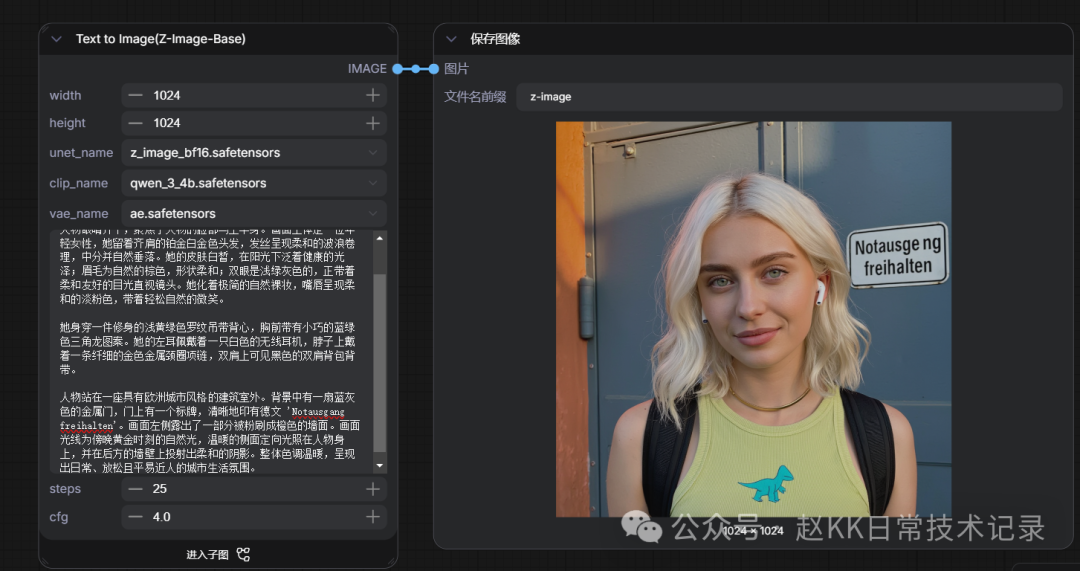
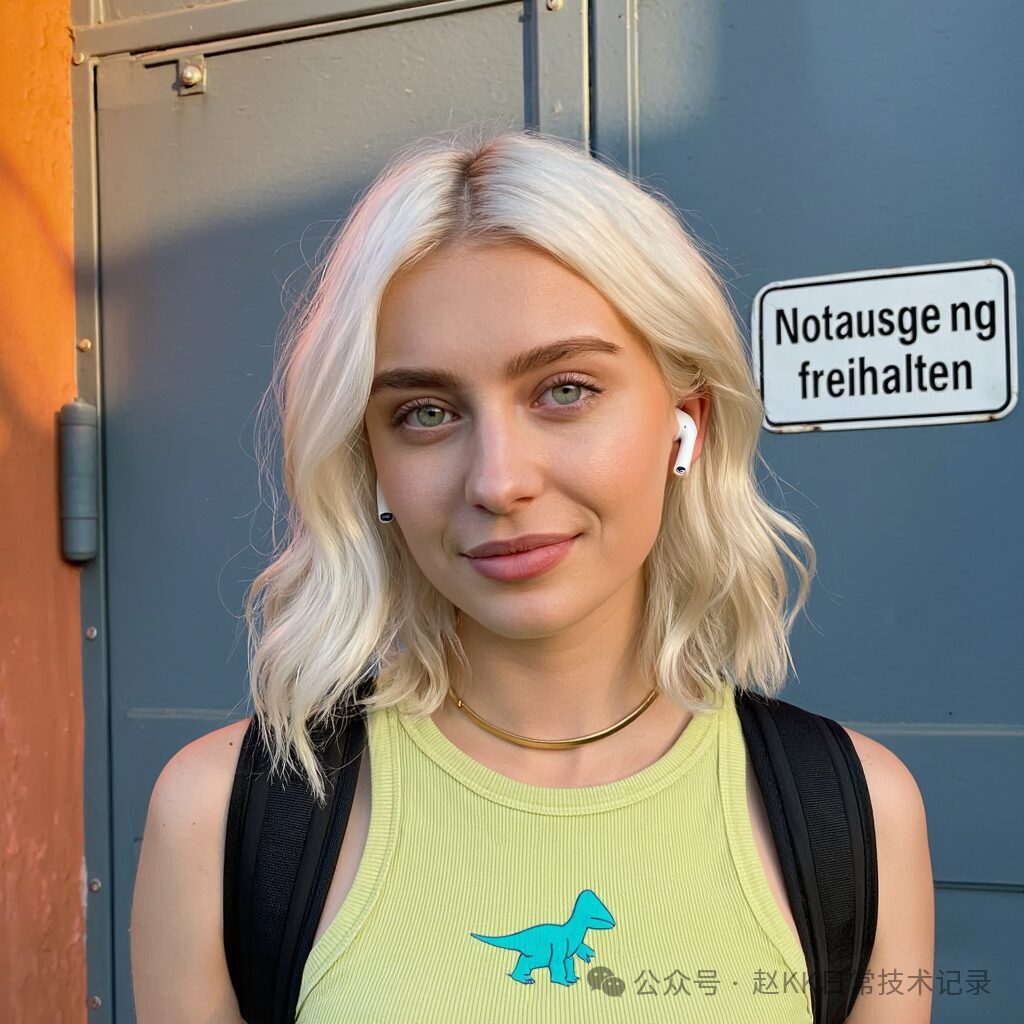
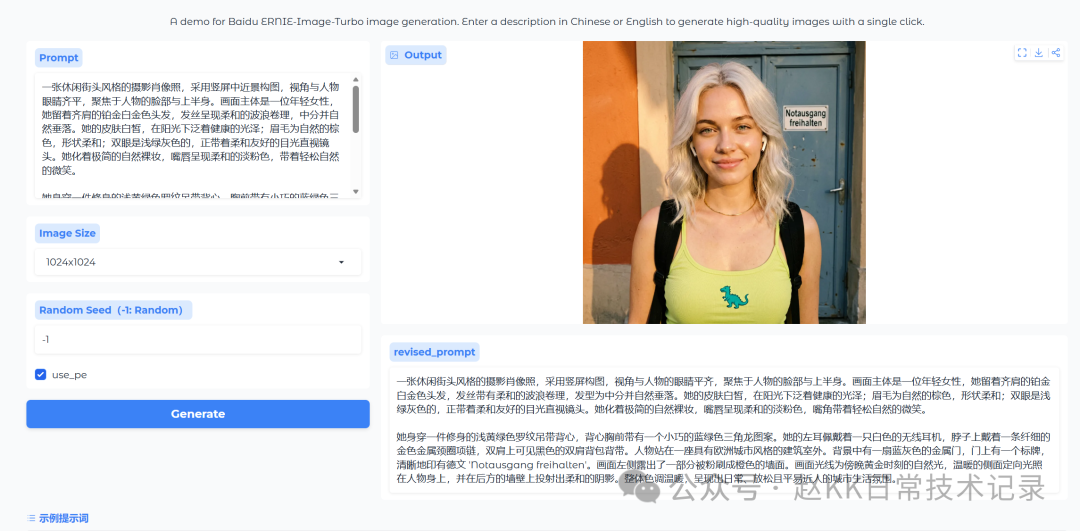
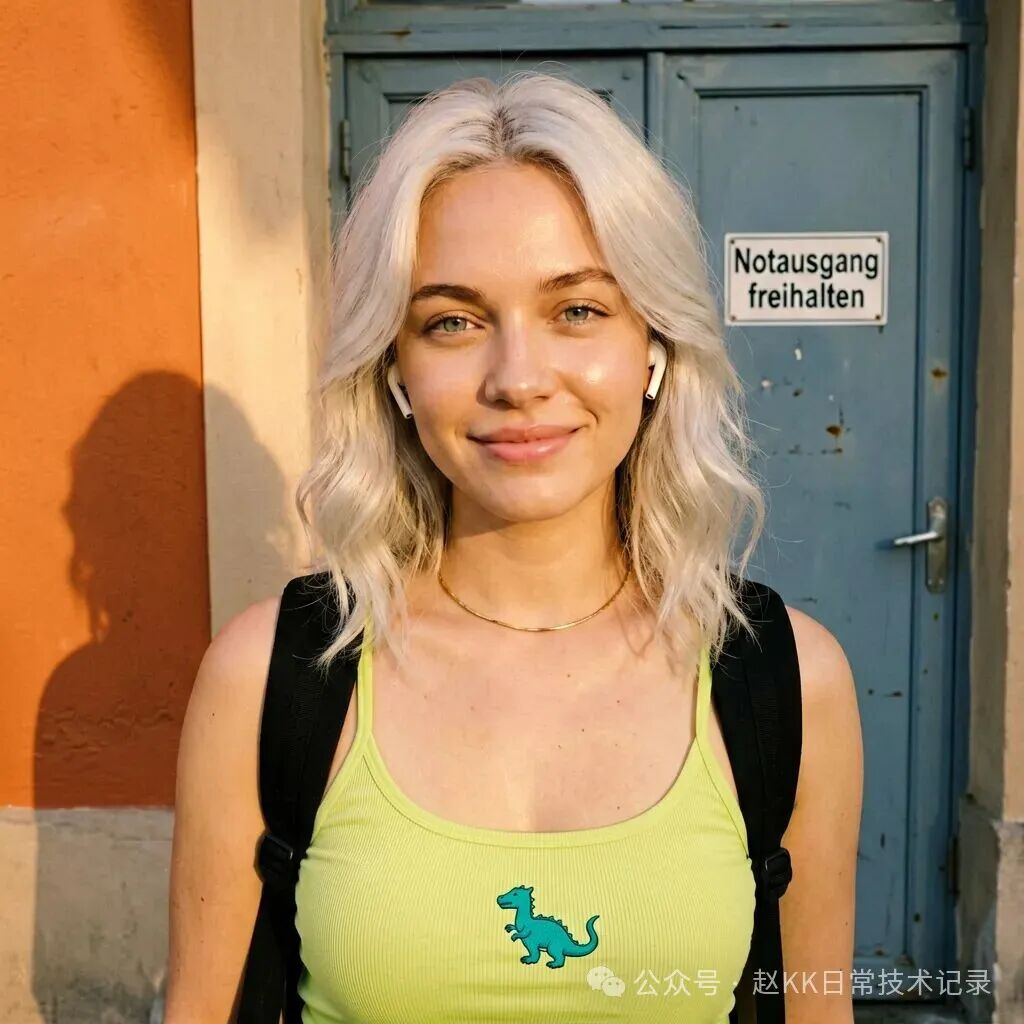
Portrait Performance Test
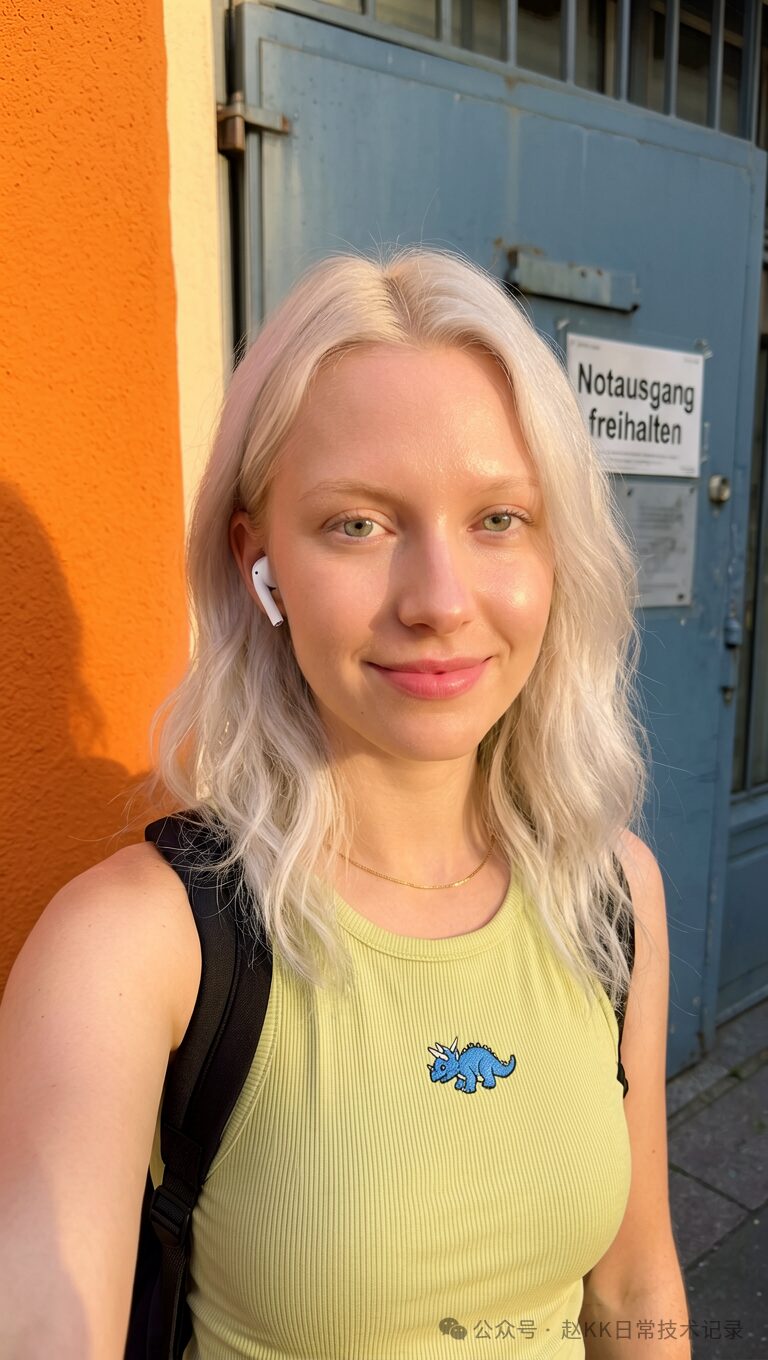
Prompt
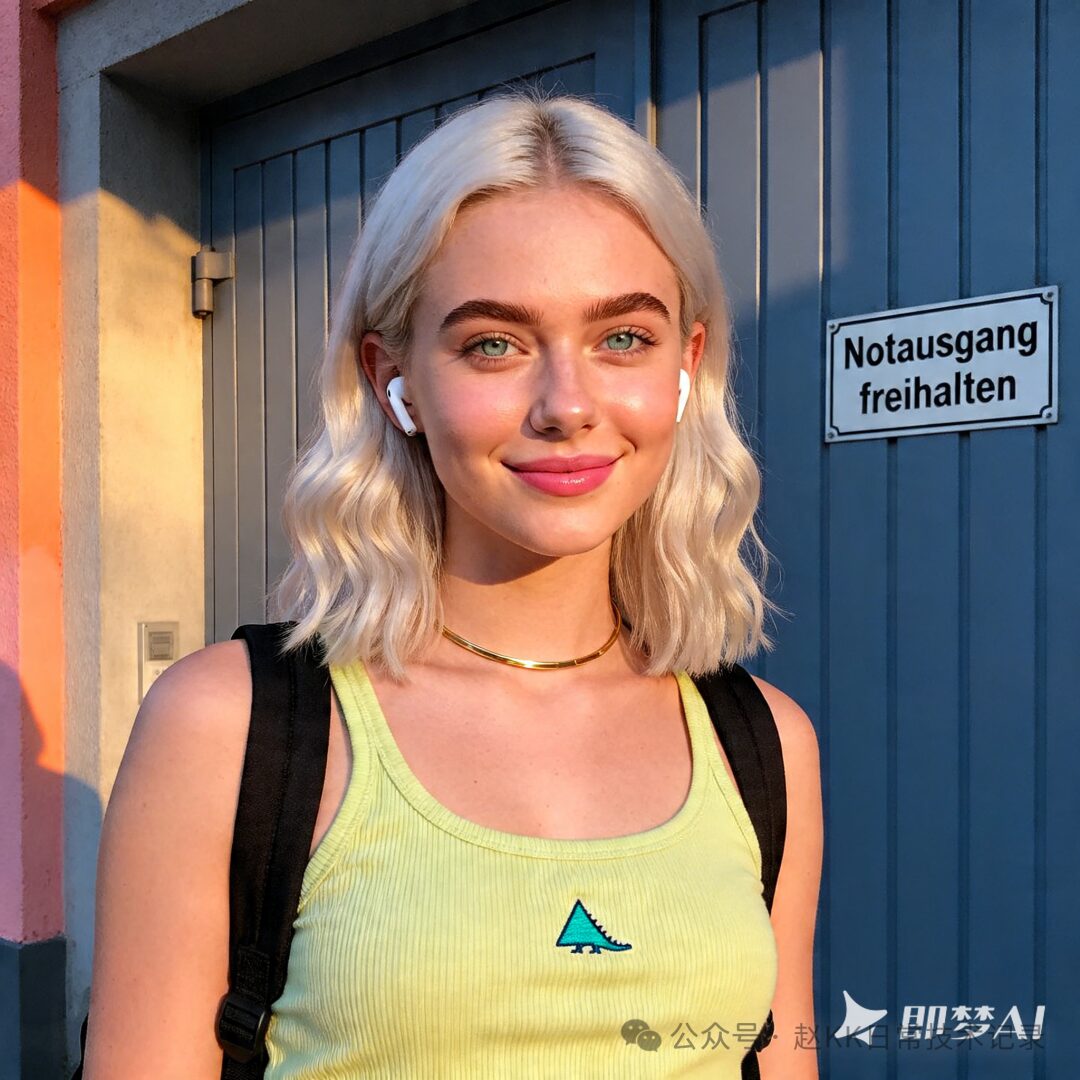
A casual street-style photography portrait, vertical medium-close-up composition, eye-level angle, focused on the person's face and upper body. The subject is a young woman with shoulder-length platinum blonde hair in soft wave curls, parted in the middle and naturally falling. Her skin is fair, glowing healthily in sunlight; eyebrows are natural brown and softly shaped; eyes are light green-gray, looking directly at the camera with a soft, friendly gaze. She wears minimal natural nude makeup, lips in soft pale pink, with a relaxed, natural smile. She wears a fitted light chartreuse ribbed tank top with a small teal triangle dinosaur graphic on the chest. Her left ear has a white wireless earbud, and she wears a thin gold metal choker necklace. Black backpack straps are visible on her shoulders. She stands outdoors in front of a European-style building. In the background is a blue-gray metal door with a sign clearly printed with German text 'Notausgang freihalten'. Part of an orange-painted wall is visible on the left. Lighting is golden hour natural light — warm, directional side light hits the person and casts soft shadows on the wall behind. Overall warm tones, presenting a casual, relaxed, approachable urban lifestyle atmosphere.
Official Result
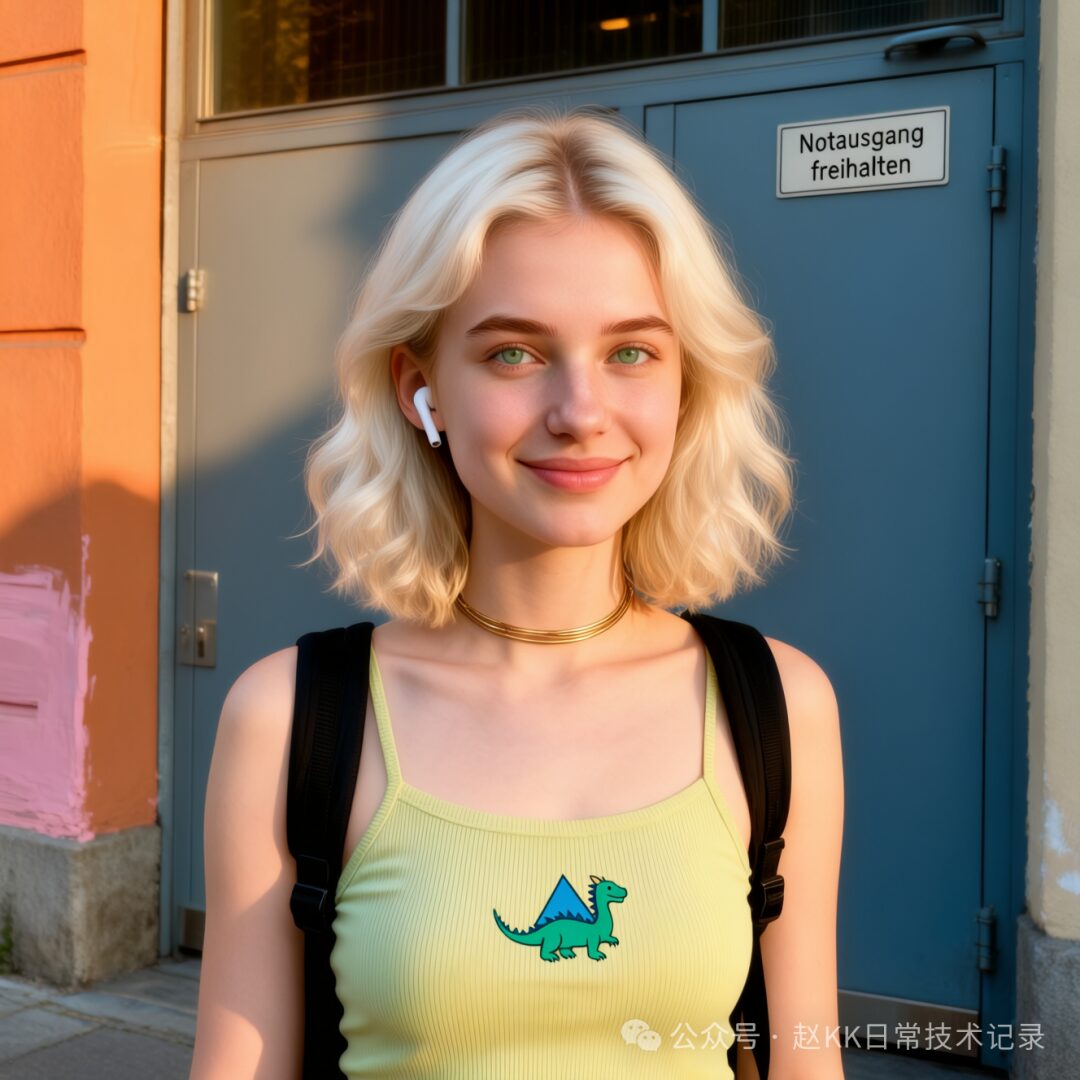
Baidu ERNIE-Image Reproduction
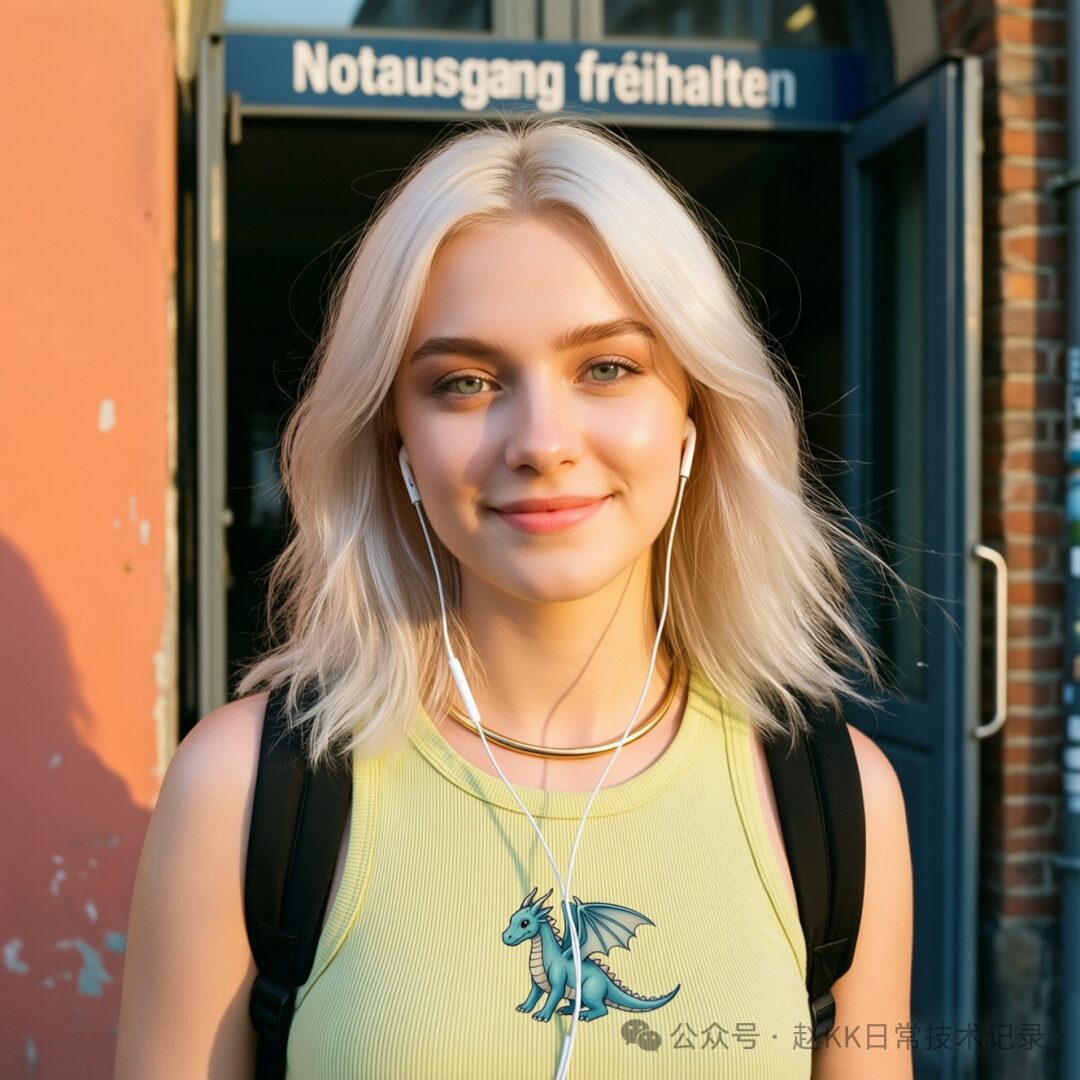
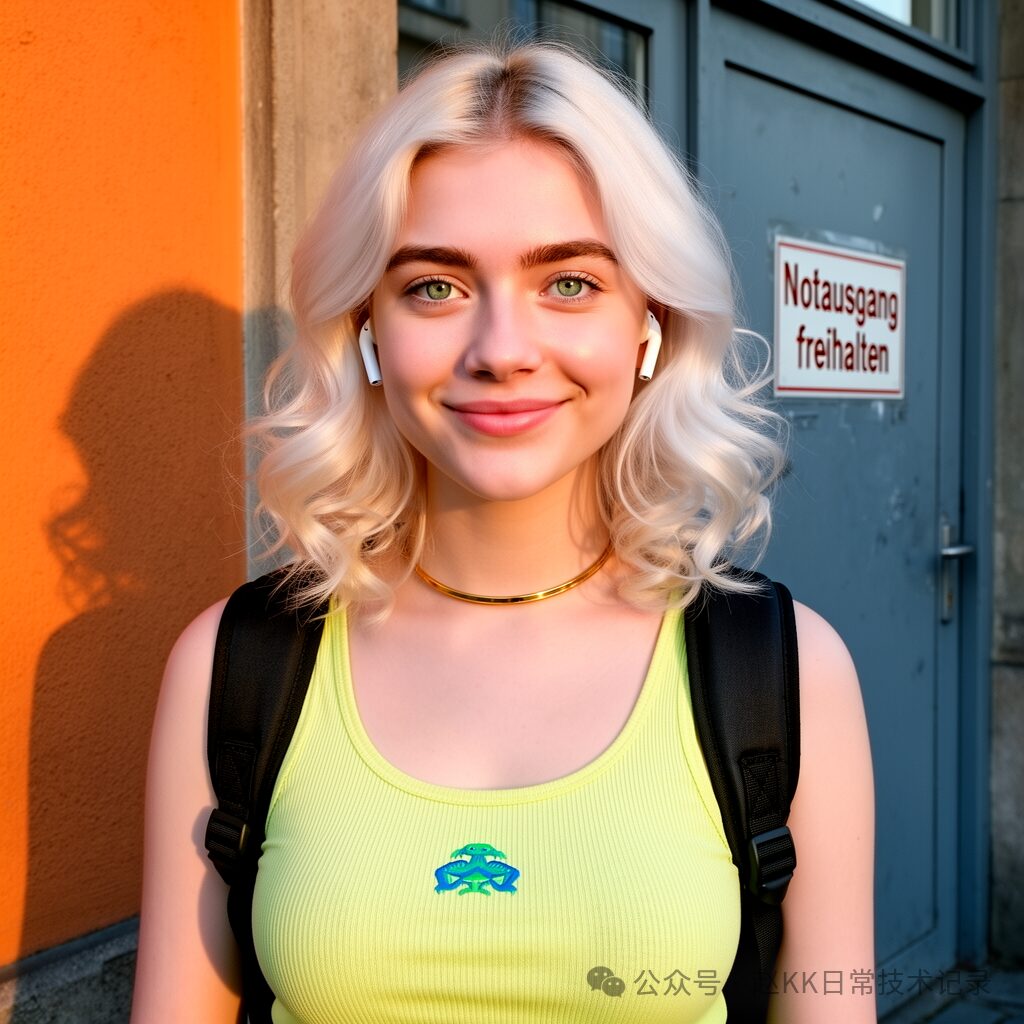
Z-Image
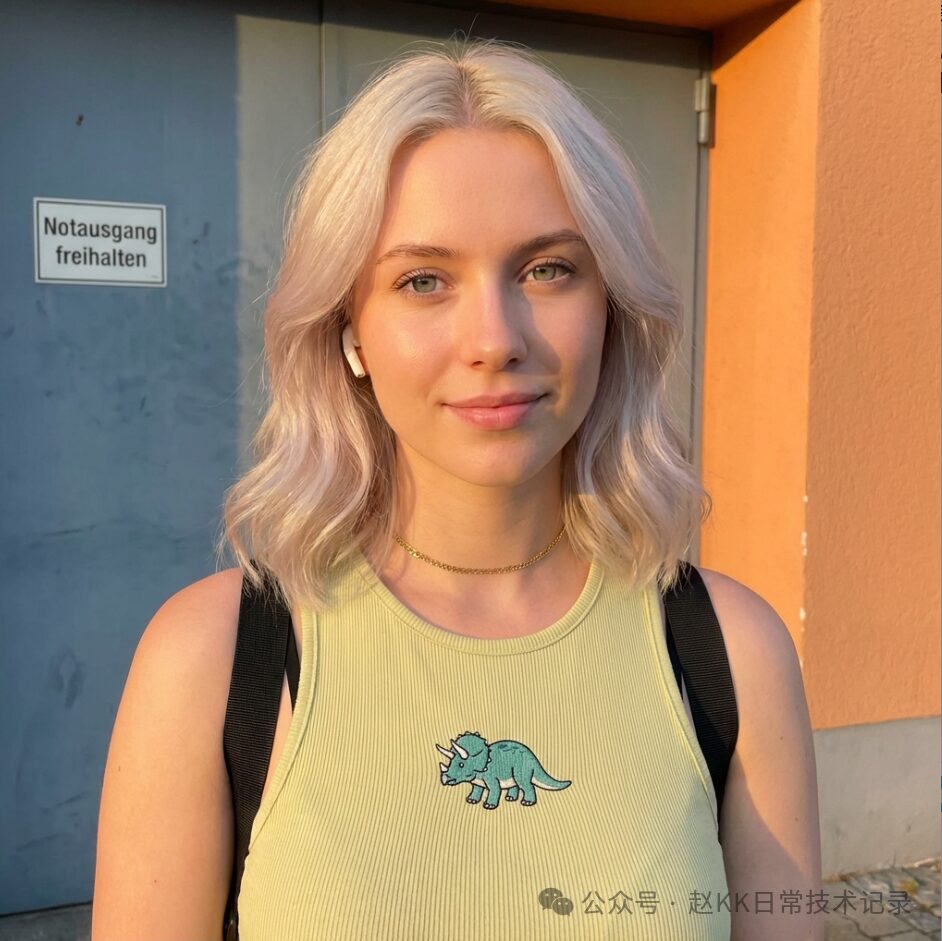
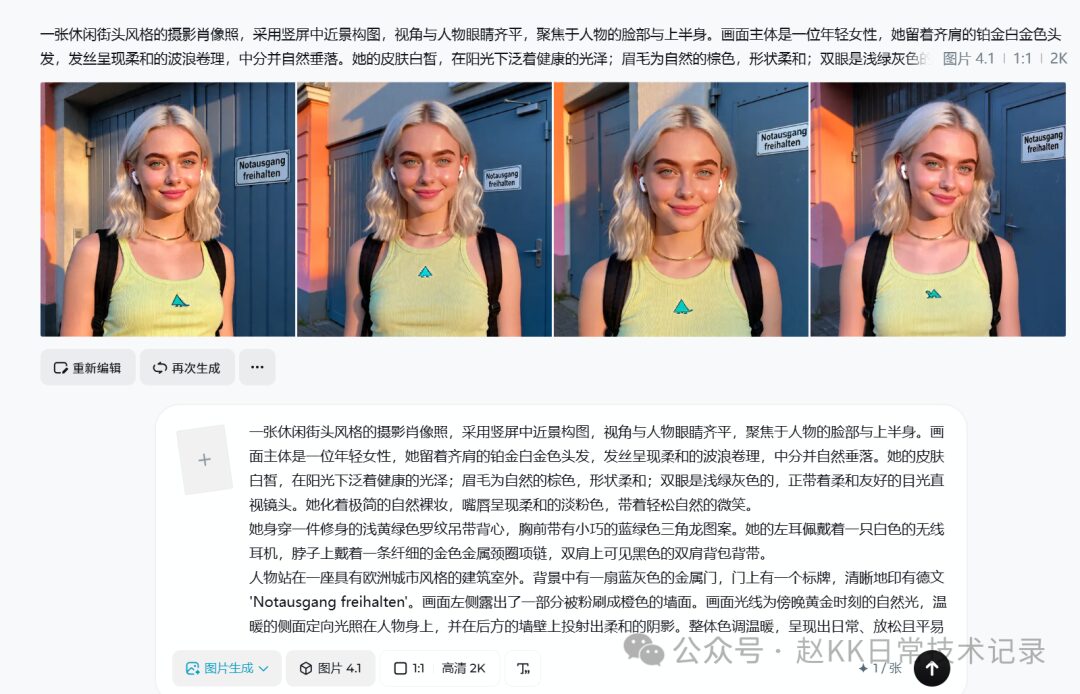
FireRed Qwen-Image-2512
Flux2
Nanobana 2 pro
Jimeng (即梦)
Portrait Test 2
Prompt
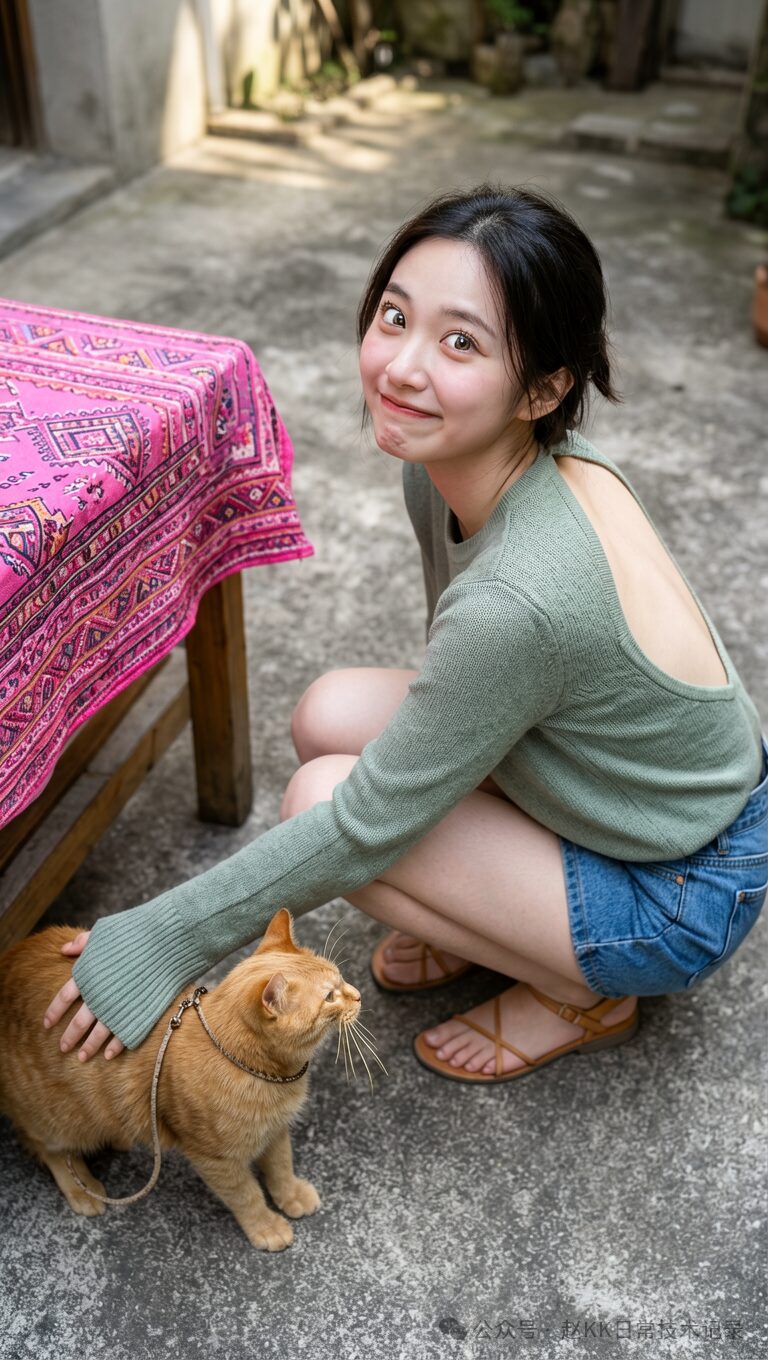
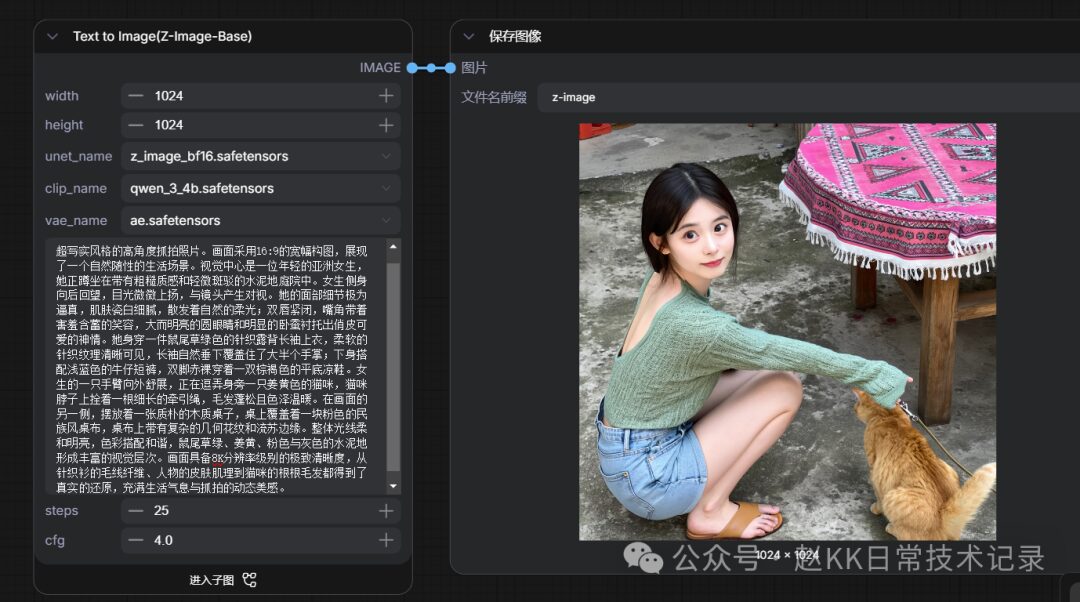
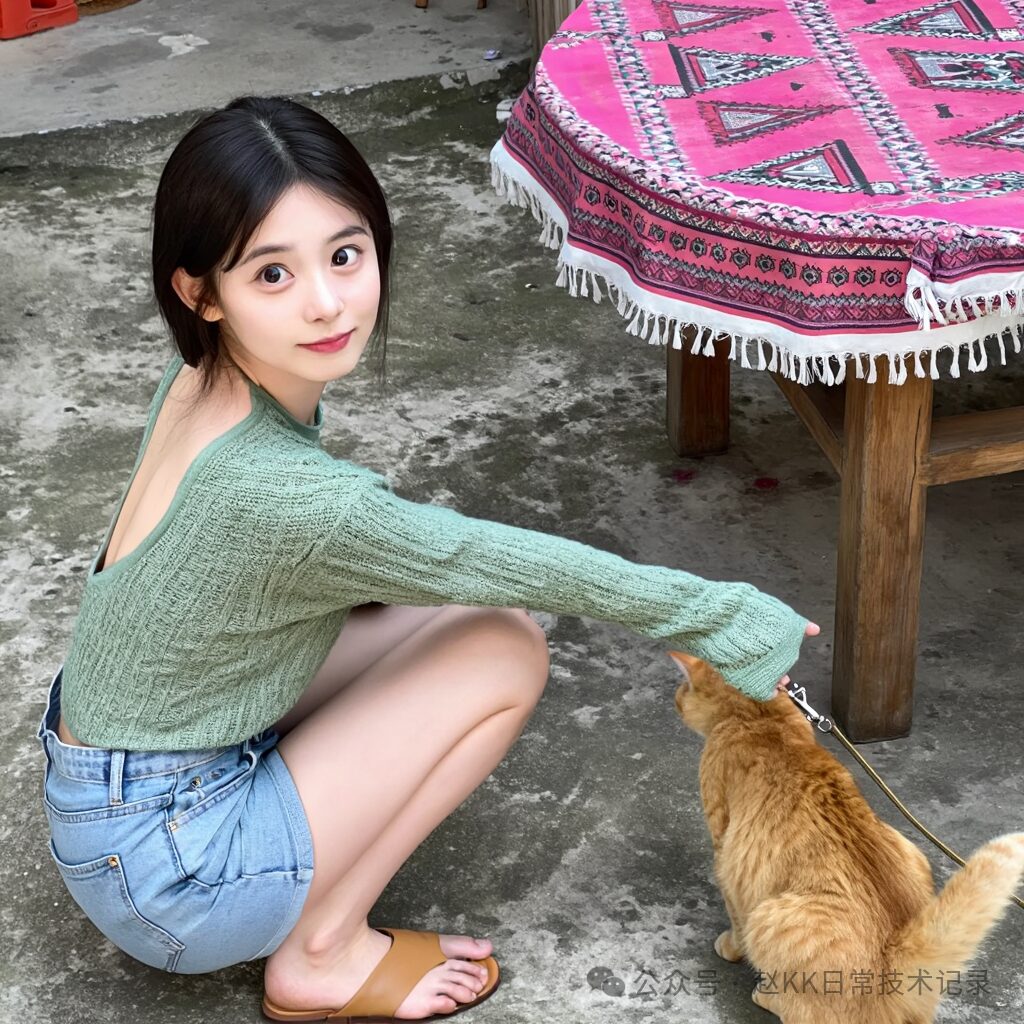
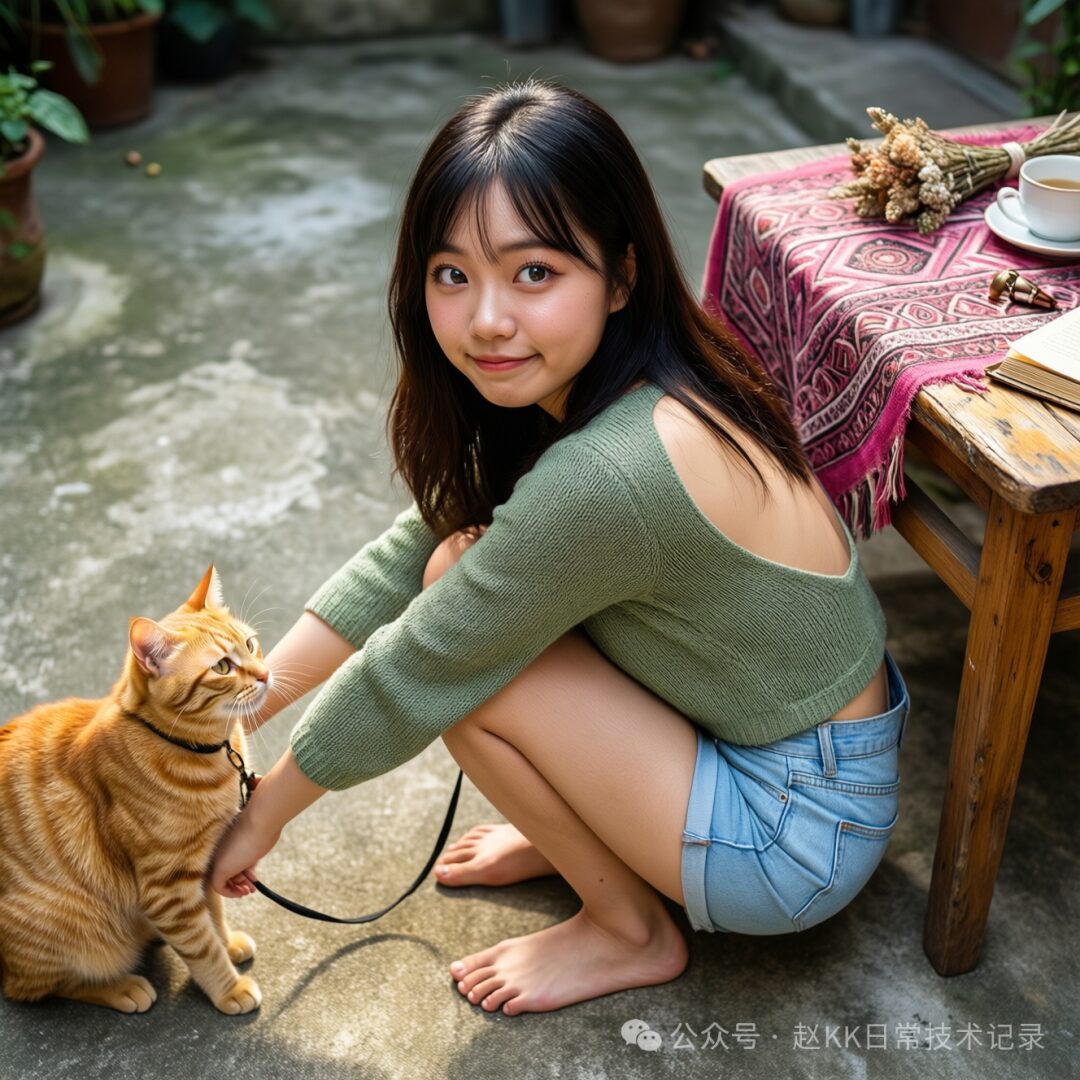
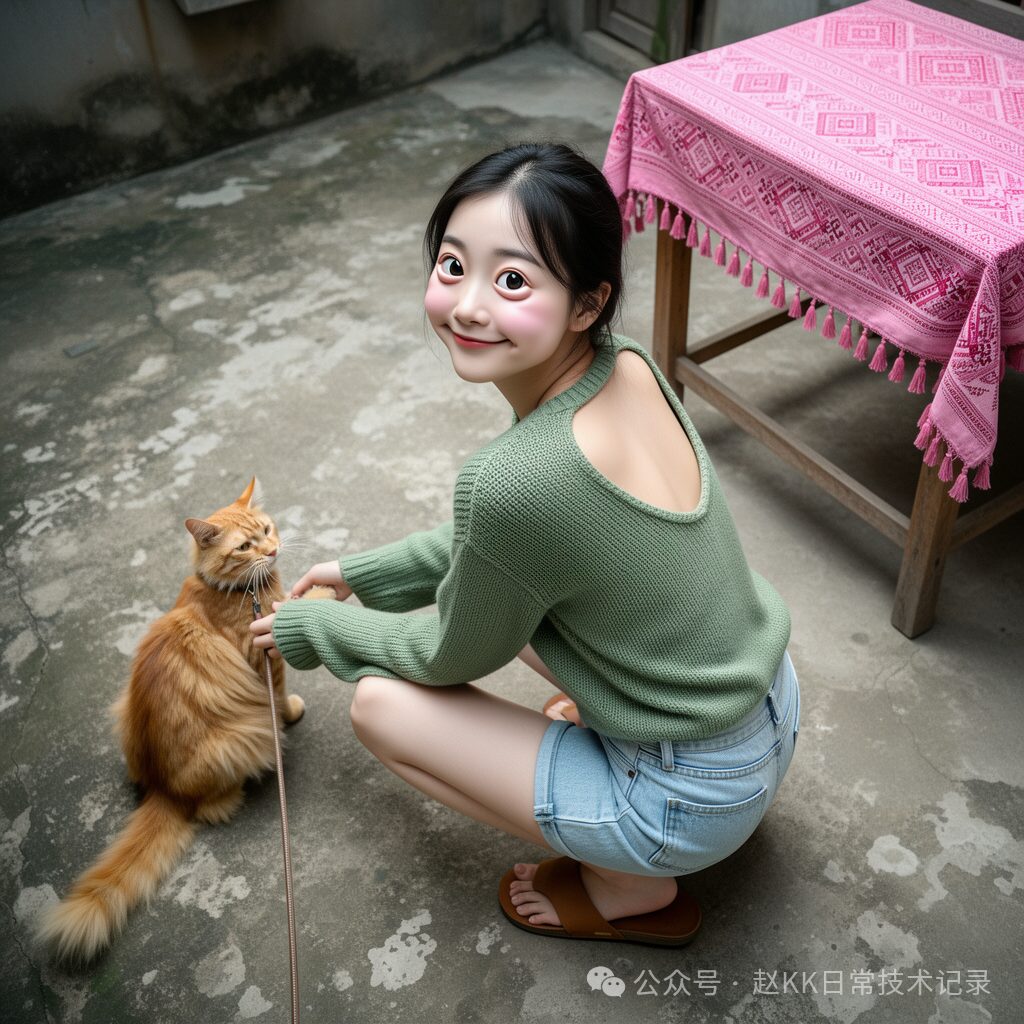
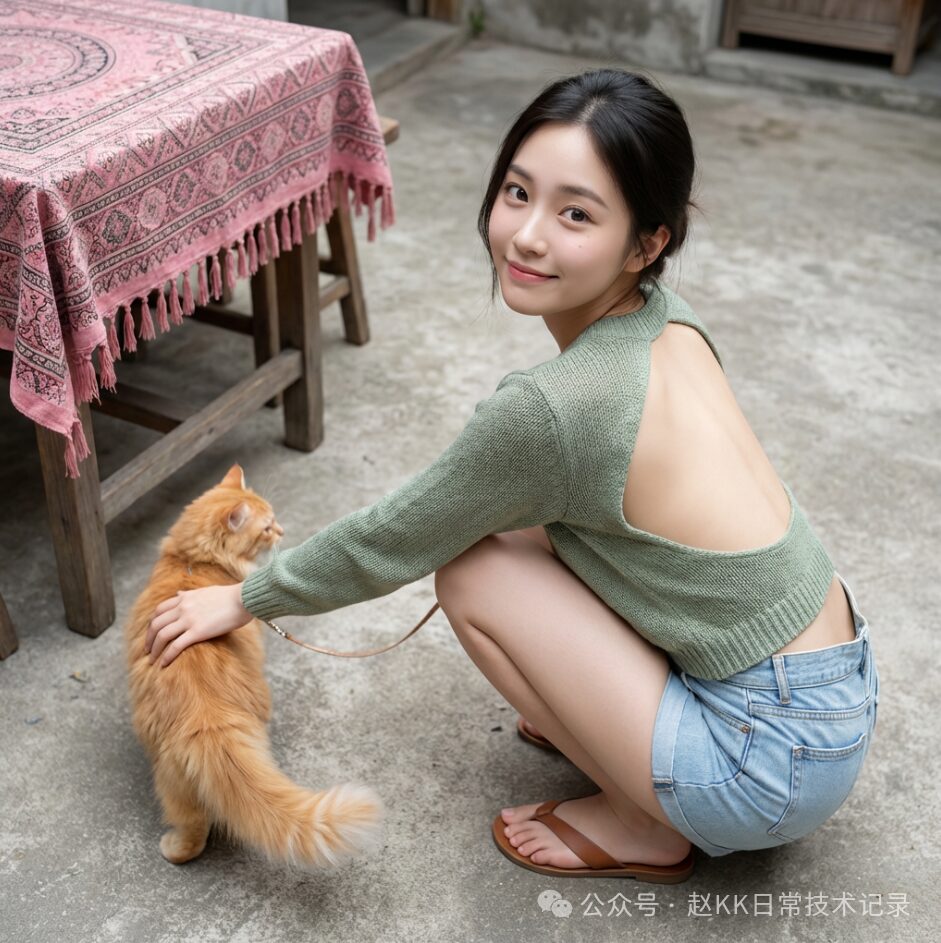
Hyper-realistic high-angle snapshot. 16:9 wide composition showing a natural, casual lifestyle scene. Visual center is a young Asian girl crouching in a concrete courtyard with rough texture and slight mottling. She turns backward, looking up slightly, making eye contact with the camera. Her facial details are extremely realistic — porcelain-white smooth skin with natural soft glow; lips closed with a shy, subtle smile; large bright round eyes and prominent eye bags conveying a playful, cute expression. She wears a sage green knitted long-sleeve backless top with clearly visible knit texture, long sleeves naturally covering most of her palms; paired with light blue denim shorts, barefoot in brown ochre flat sandals. One arm extends outward, playing with a tortoiseshell-colored cat beside her — the cat has a thin leash and fluffy, warm-toned fur. On the other side of the frame sits a rustic wooden table covered with a pink ethnic-style tablecloth featuring complex geometric patterns and fringed edges. Overall lighting is soft and bright, colors harmonious — sage green, tortoiseshell, pink, and gray concrete create rich visual layers.
Comparison Results Across Models
Official Result
Baidu ERNIE-Image Reproduction
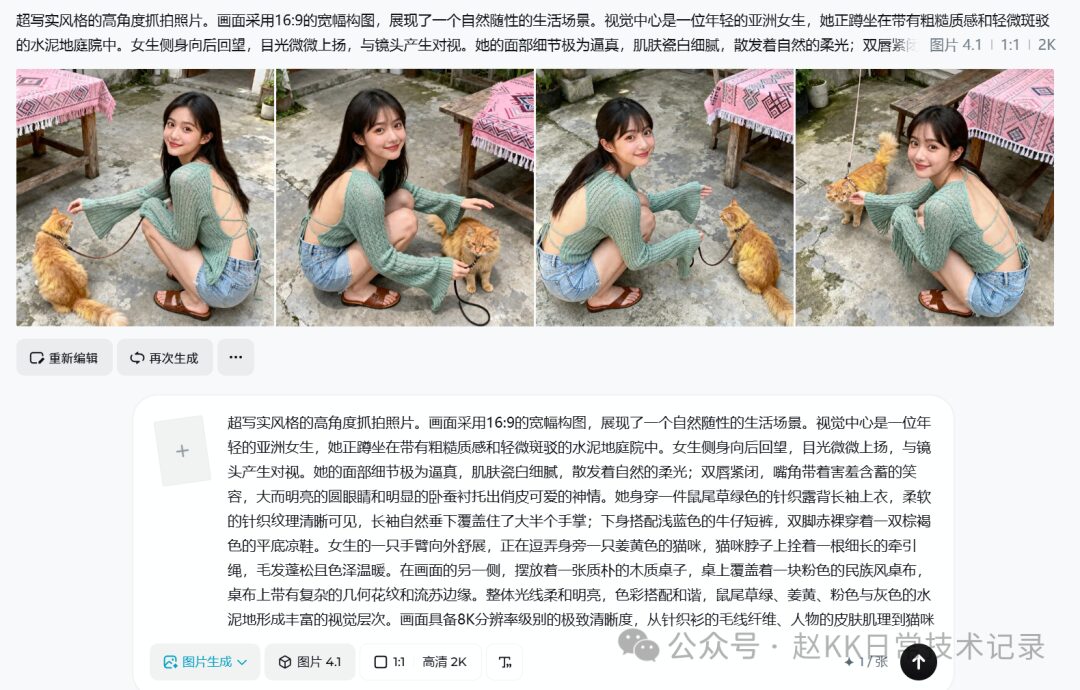
Z-Image
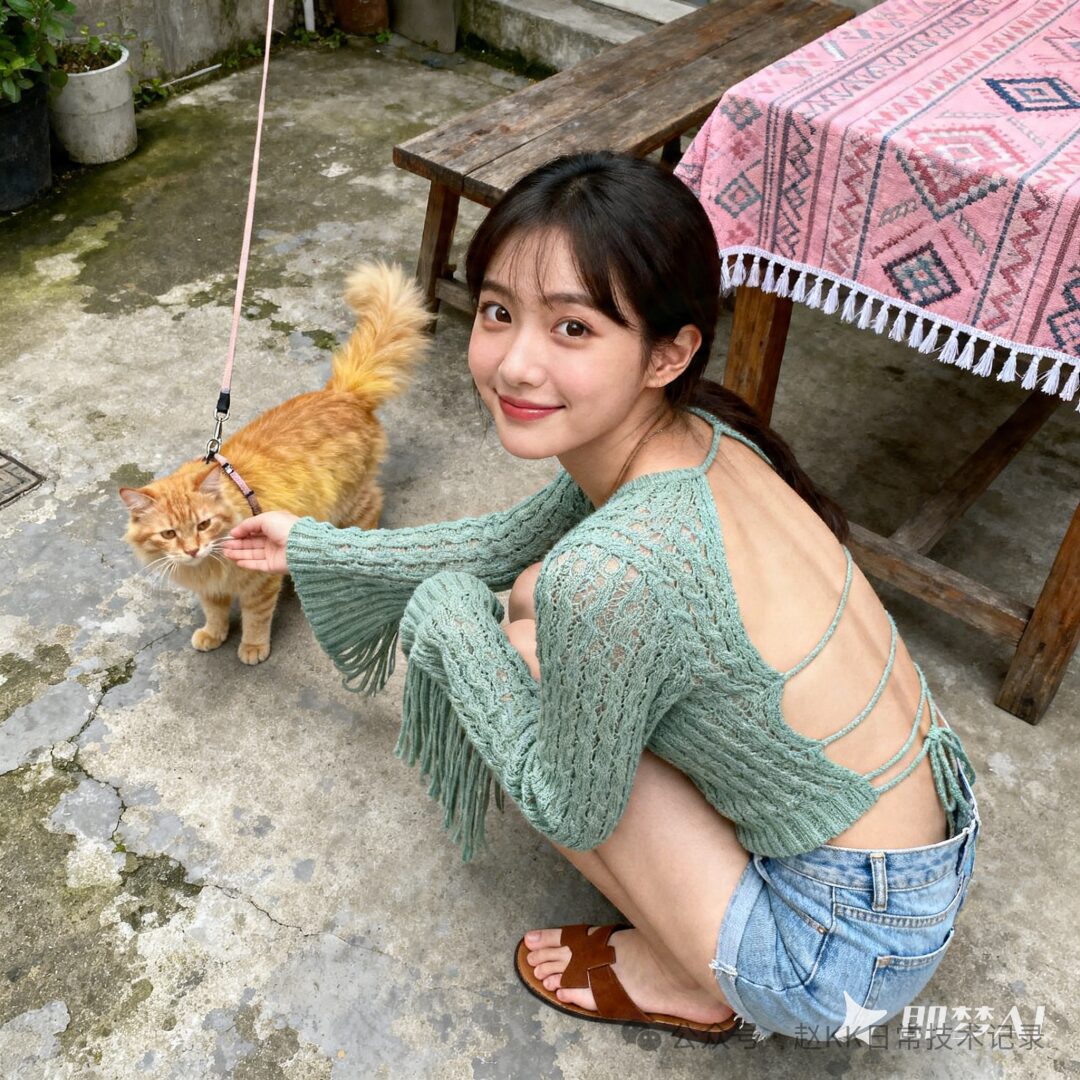
FireRed Qwen-Image-2512
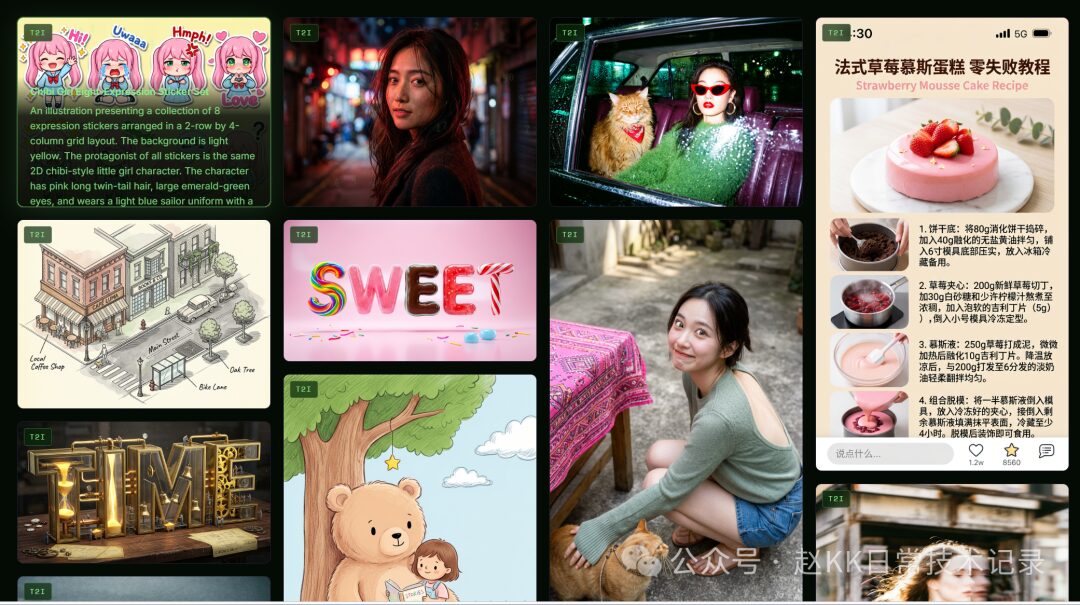
Flux2
Nanobana 2 pro
Jimeng (即梦)
Summary
From the multiple comparison tests above:
- ERNIE-Image excels at official prompt reproduction, especially leading in Chinese text rendering, structured layout, and complex instruction following
- The built-in 3B Prompt Enhancer is a differentiated highlight, significantly improving short-prompt generation quality
- In Chinese scenarios, ERNIE-Image clearly outperforms most international models, competing fiercely with Chinese-optimized models like Jimeng
- In portrait generation, ERNIE-Image performs well in skin texture and lighting, though still has gaps with top-tier models
Source: 赵KK日常技术记录 (WeChat Official Account)
Published: April 14, 2026